

Digitize Today, Dominate Tomorrow
-
 Send Us Mail
-
 Call 24/7 Hours
+91 9277 802030

A strong DevOps engineer interview tests whether someone can change a running system safely, diagnose an incident with evidence and leave reliable operating instructions. Use a small production-like scenario, explicit constraints and a common scorecard. Evaluate release judgment, infrastructure changes, observability and access boundaries alongside scripting ability.
Research reviewed: 18 October 2026. Interview format and weights below are AppZime Technologies’ illustrative recommendations, not a validated hiring benchmark.
“DevOps” can describe release automation, cloud infrastructure, platform tooling or reliability work. Begin by naming the responsibility you need: maintaining a deployment platform, improving build repeatability, managing a cloud environment or joining a sustainable on-call rotation. These needs overlap, but they do not imply the same seniority or experience.
This guide helps engineering leaders and technical recruiters evaluate contractors or permanent engineers. It is intended for teams with an application already in development or production. It does not turn an interview into authorization to access live systems, and it makes no claim about salaries or candidate availability in a particular Indian city.
Write the current architecture, failure impact, release cadence and ownership boundary in the interview brief. If the organization has no release owner or incident process, acknowledge that gap. A new engineer cannot compensate for missing product decisions by adding another automation tool.
| Need | Interview emphasis | Ownership question |
|---|---|---|
| Release engineering | Build integrity, promotion and rollback | Who can approve a production change? |
| Cloud infrastructure | Identity, networking, infrastructure review and recovery | Who owns state and privileged access? |
| Platform engineering | Usable defaults, self-service and adoption | Who supports the internal platform? |
| Reliability engineering | User impact, service objectives and incident learning | Who carries the pager and has authority to mitigate? |
Illustrative fictional example — not an AppZime Technologies client project or measured result. A subscription application runs an API and worker service on Kubernetes, backed by PostgreSQL and a queue. A release increases error responses and queue age. The application is available to customers, and the interviewer supplies sanitized logs, metrics and configuration snippets.
The candidate has no production credentials. Their task is to propose the next observations, choose a reversible mitigation and explain how the team would release a permanent fix. Tell them that the latest application change includes a database migration, so a blind rollback may be unsafe. Do not withhold that fact as a trick.
For an illustrative 80-minute session, reserve 15 minutes for architecture and responsibility mapping, 25 for the incident, 20 for a deployment or infrastructure change review, ten for security and ten for a handover. Permit official documentation and state any policy on AI assistance before the session.
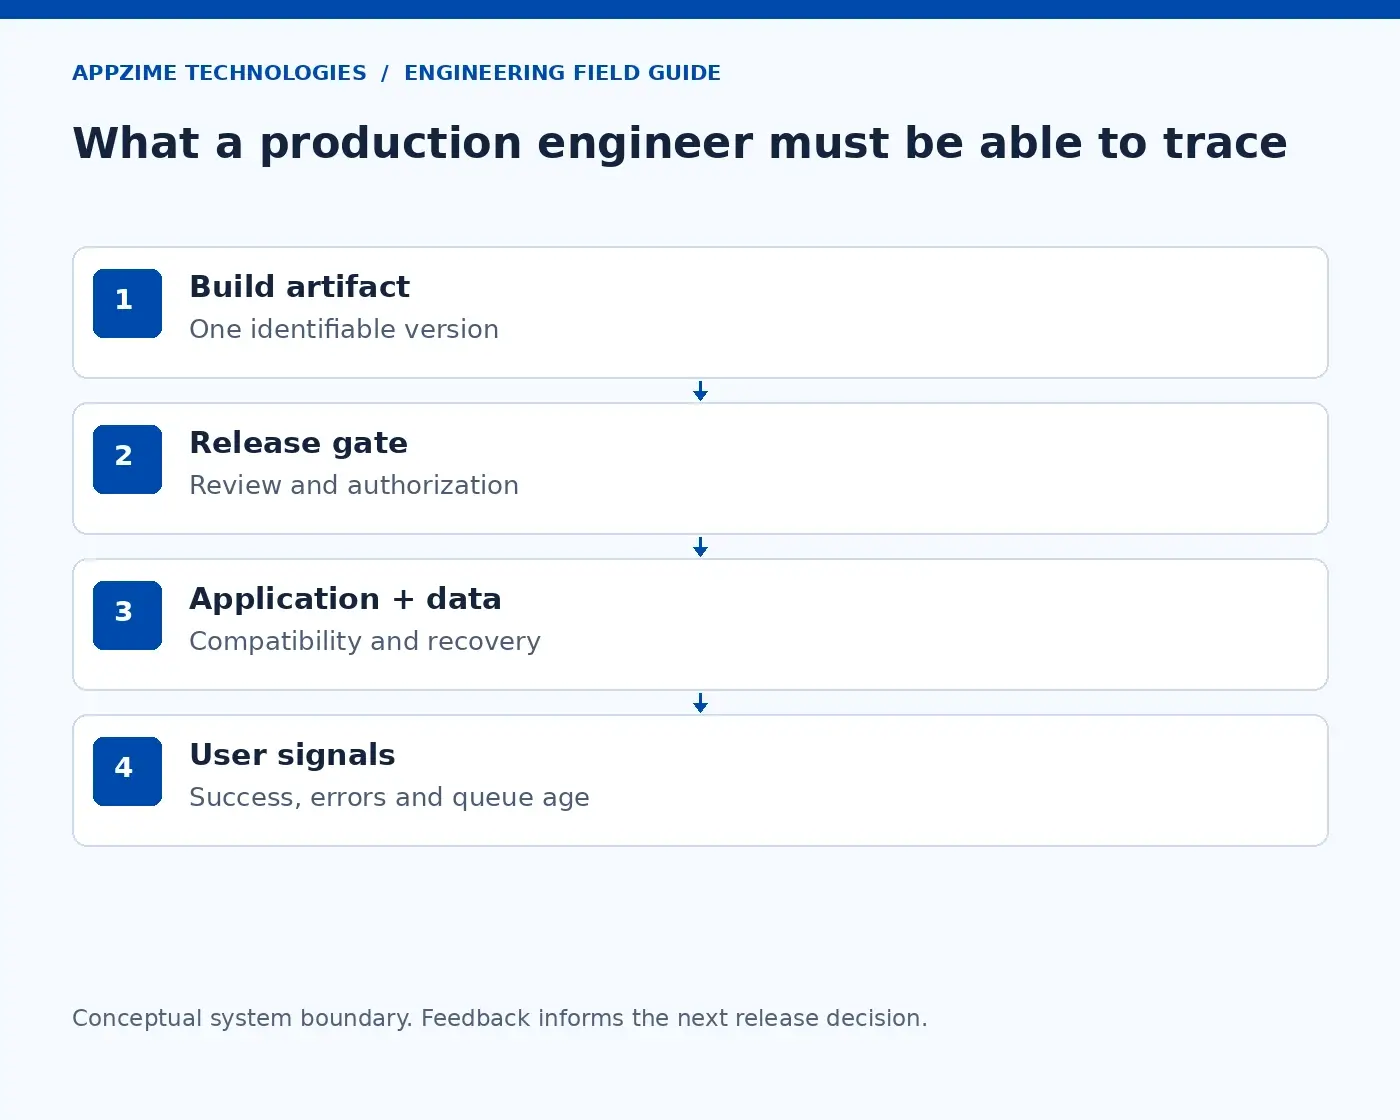
The operating boundary includes the build artifact, promotion gate, application, data store and feedback signals. The team should be able to identify which component changed and what evidence links that change to the customer symptom. A tool-name answer does not establish that reasoning.
A capable response starts with customer impact and safety. What is failing, for whom and since when? What changed? Is there an incident lead? What actions are already in progress? The candidate should avoid parallel, unrecorded configuration changes that destroy evidence or make the incident harder to understand.
Supply a short timeline: a release began at 10:00, request failures increased at 10:03 and queue age rose at 10:06. Correlation makes the release a useful hypothesis, not a proven root cause. Ask which logs or traces would distinguish a failing dependency from a bad application rollout.
Then ask for a mitigation with a verification condition. Pausing further rollout may be sensible. Reducing a nonessential workload may protect a shared resource. Reverting application code may help only if compatibility with the new schema has been established. A strong engineer explicitly names that prerequisite.
Evaluate whether the candidate communicates uncertainty. “The release probably caused it; I will compare failing requests with the previous version and check migration compatibility before rollback” is more useful than immediate certainty based on one graph.
Present a service whose liveness probe checks a slow external dependency. Ask what could happen when that dependency becomes unavailable. Repeated container restarts can add disruption without fixing the external failure. The candidate should consider the purpose of each probe and the application’s actual recovery behavior.
The Kubernetes probe documentation distinguishes readiness, liveness and startup checks. Readiness controls whether a Pod is considered ready to receive traffic; failed liveness checks can cause restarts, and startup checks can protect slow initialisation. Ask for workload-specific thresholds rather than copying a manifest from memory.
For the fictional API, require an explanation of dependency failure, warm-up behavior and how terminating instances finish in-flight work. For the worker, ask about duplicate message processing, acknowledgement order and graceful shutdown. Increasing the replica count is not a reliable answer when every worker shares the same bottleneck.
Give the candidate a sanitized infrastructure plan that replaces a stateful resource and broadens an identity policy. Ask them to identify impact, dependencies, approvals and a recovery plan. They should inspect the difference, explain why replacement is proposed and ask whether backups have actually been restored in a test.
Ask where infrastructure state is stored and who can read it. HashiCorp’s Terraform guidance explains that state and plan files can contain secrets; marking a value sensitive primarily controls display, and does not by itself remove it from stored state. The interview should test this distinction without asking candidates to reveal any real credentials.
Good evidence includes a reviewed plan, controlled apply permissions, protected state storage and an understanding of drift. A rehearsed recovery step is stronger than “we can recreate everything.” Recreating compute does not automatically restore database contents, customer data or external configuration.
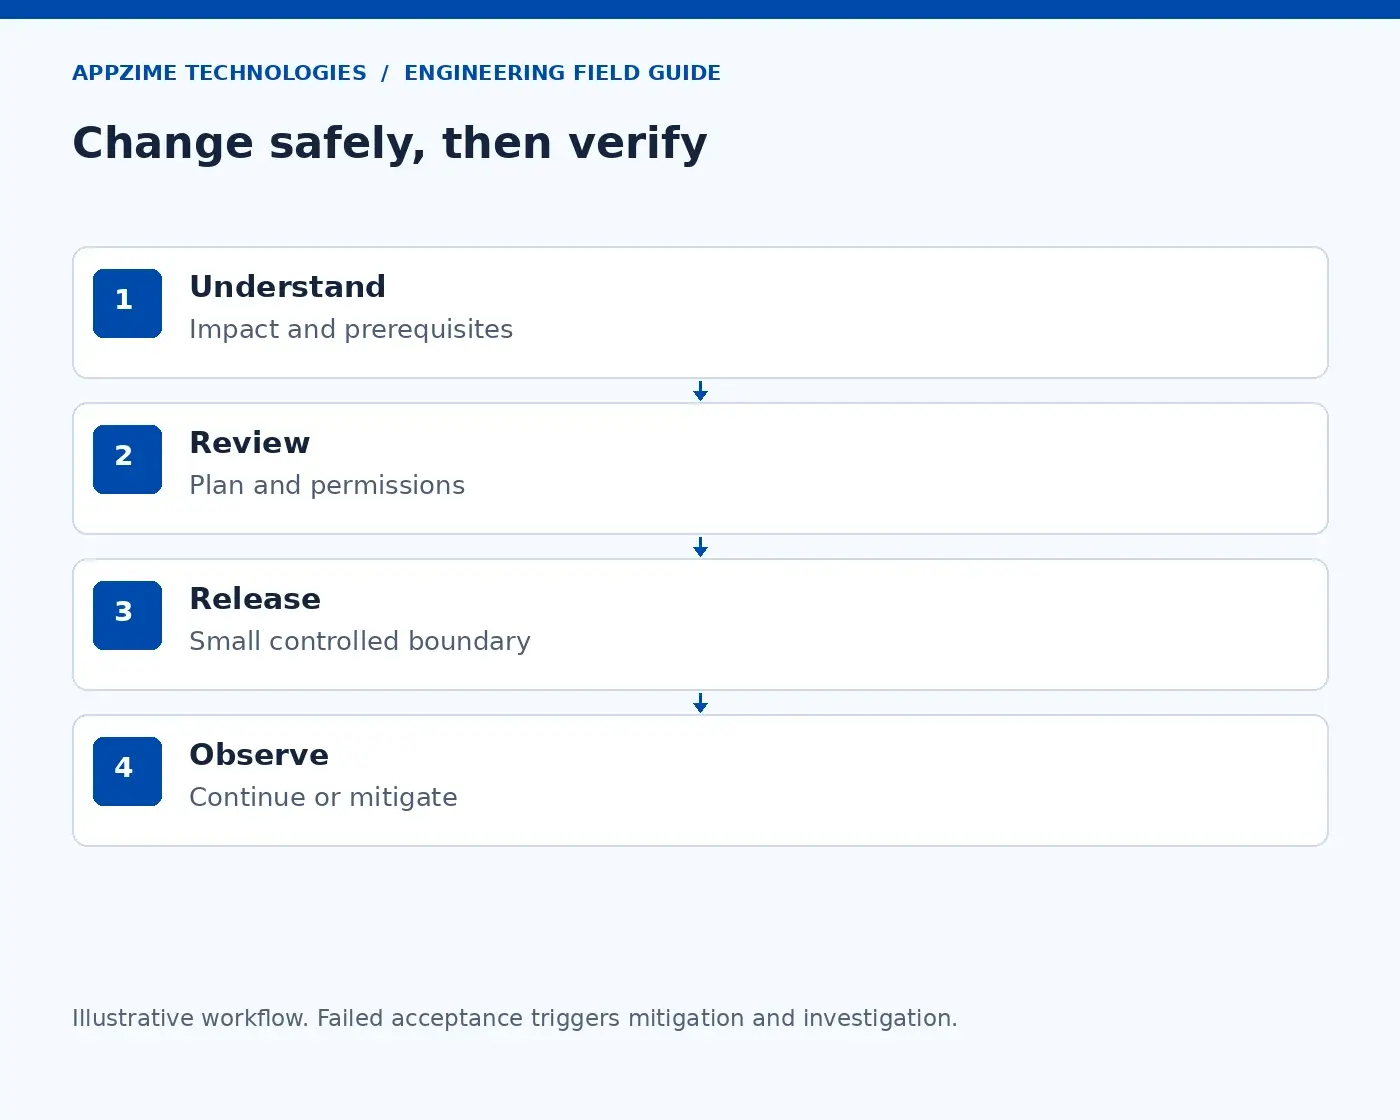
A safe change has a sequence: understand impact, review the candidate change, release within a controlled boundary, observe customer outcomes and either continue or mitigate. Every decision needs an owner. The diagram is a conceptual operating workflow rather than a universal tool configuration.
Show two alerts: CPU is elevated, and successful checkout requests are declining. Ask which needs a page and what additional context matters. A mature answer considers sustained user impact, service-level objectives, traffic and whether an actionable runbook exists. An alert that wakes someone should support a useful response.
Google’s SRE Workbook chapter on alerting describes error-budget burn and multiple observation windows. Use it as a reasoning reference, not a demand to memorize thresholds. The chapter also discusses low-traffic services, where a small number of failures can distort rate-based signals.
For a simple interview calculation, suppose an illustrative request-based objective permits a 0.1% error fraction. If an observation window shows 1% errors using the same event definition and denominator, the error-budget burn rate is ten. This calculation does not establish an SLA, tell you when a production page should fire or prove that the service has enough traffic for a stable signal.
Ask how a build pipeline authenticates to its cloud environment. The candidate should distinguish a person’s login from a workload identity and explain the trust boundary. Broad, long-lived administrator credentials copied into every project create a difficult ownership and revocation problem.
GitHub Actions supports OpenID Connect for obtaining short-lived cloud access tokens from compatible providers after a trust relationship has been configured. Ask how the allowed repository, branch or environment is restricted and how the resulting cloud role is scoped. “We use OIDC” is insufficient if any workflow can assume a powerful role.
Compare that response with AWS IAM recommendations on temporary credentials, least privilege and access review. Discuss the principles; the interview is not a request to change your company’s identity settings. Any eventual implementation needs review against the actual platform and account model.
The example below totals 100 points. Score each area from zero to four, then scale by its weight. Zero means no usable evidence, two means a functional response with important gaps, and four means well-explained decisions with recovery and limitations. Do not average away a critical safety gap.
| Area | Illustrative weight | Observable evidence |
|---|---|---|
| Incident reasoning | 25 | Impact, hypotheses and reversible mitigation |
| Release safety | 25 | Compatibility, verification and rollback constraints |
| Infrastructure ownership | 20 | Reviewed change, protected state and recovery |
| Security judgment | 20 | Scoped identity and explicit access boundaries |
| Communication and handover | 10 | Timeline, runbook and clear uncertainty |
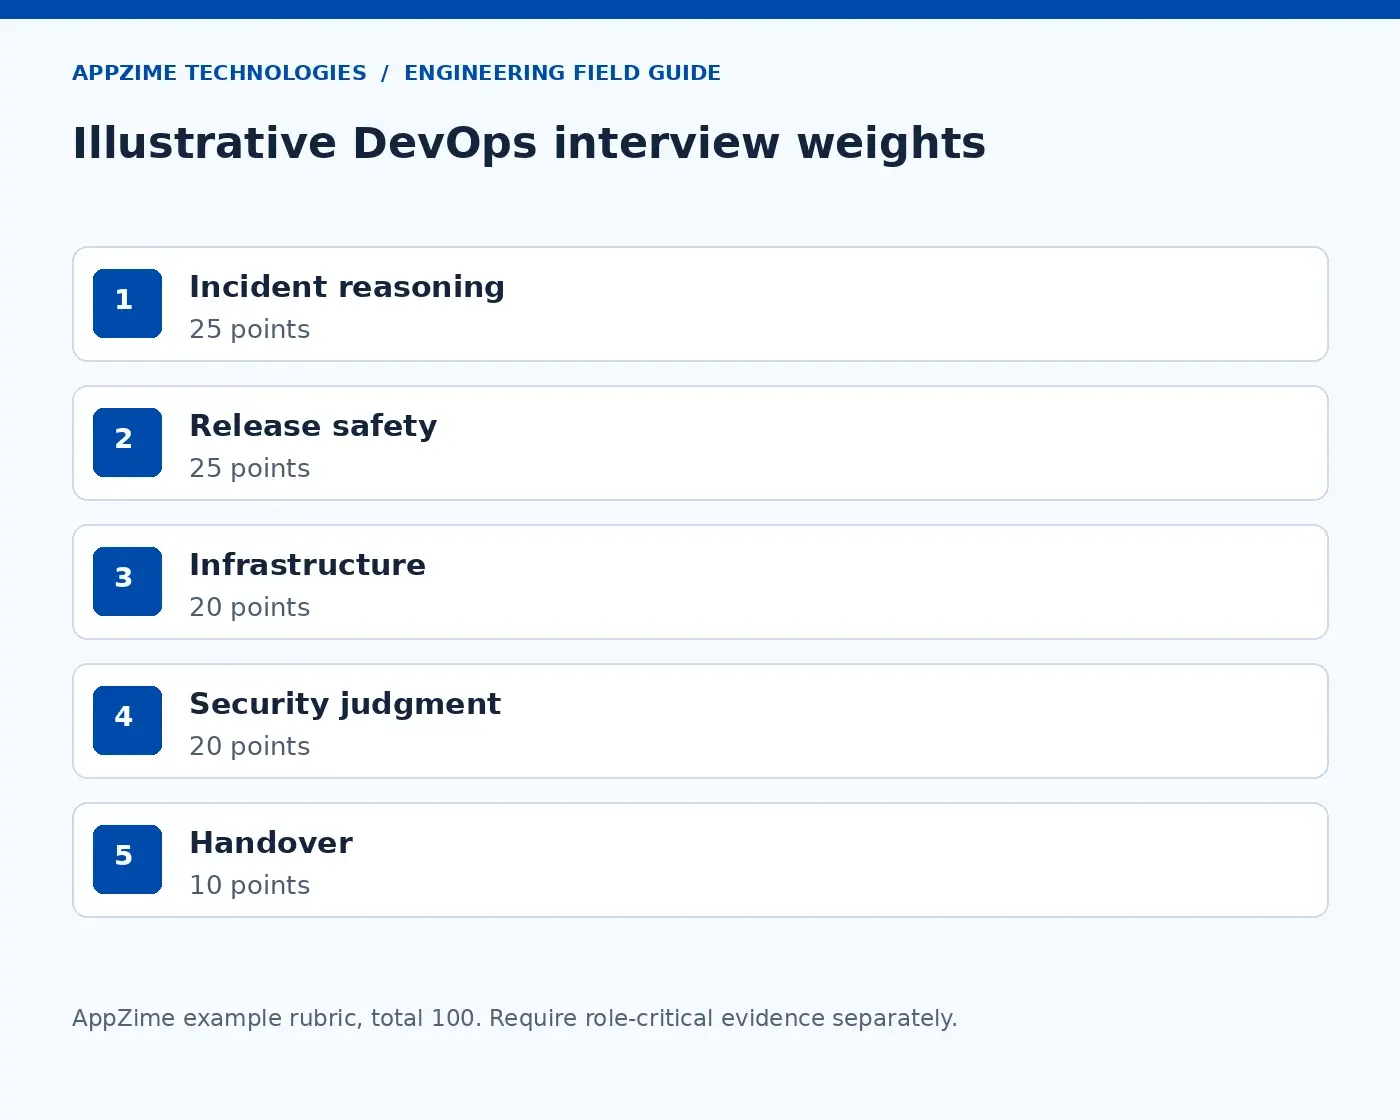
Agree the role-critical evidence before the first interview. For example, a release owner must identify migration compatibility before rollback. A junior automation engineer can have a narrower responsibility and a defined senior reviewer. Use independent evaluator notes and discuss disagreements with reference to what the candidate actually demonstrated.
Google: the published SRE Workbook describes operational practices developed from Google’s experience, including alert design and the limits of rate-based signals. It demonstrates a way to reason about reliability. It is not evidence that adopting Google’s exact parameters improves recruitment or that a smaller application needs Google’s operating model.
Airbnb: its engineering account of observability ownership describes a migration to an internal platform and associated organizational lessons. The relevant interview question is who owns instrumentation, definitions and the developer experience. Treat the account as company-reported experience, not an independently measured promise of savings for your team. These organizations are not presented as AppZime clients.
Use a contractor for a bounded migration, pipeline repair or infrastructure workstream when internal ownership exists. A dedicated platform team may be more suitable for a persistent internal product with multiple service teams. Hiring one engineer to provide uninterrupted support without backup, escalation or holiday coverage is an operating-model problem.
AppZime Technologies describes relevant DevOps and cloud services and IT staffing engagement options. Confirm the exact skills, on-call expectations, access requirements and acceptance criteria during scoping; do not infer a specific candidate’s availability from a service page.
A first-month deliverable could be one reviewed deployment path with a known artifact, documented rollback conditions, scoped deployment identity and an exercised failure scenario in a test environment. The acceptance condition is demonstrated operation, not a screenshot of a green pipeline.
Budget for interviewers, a safe sandbox, senior review, platform licenses where needed and ongoing coverage. Compare proposals by ownership and operating burden as well as bill rate. This guide supplies no salary benchmark or guaranteed completion timeline.
A certification can support evidence of learning. It does not replace a practical discussion of incidents, changes and ownership.
Only when proportionate. Reviewing a small, flawed pipeline can expose judgment more efficiently than building a complete system during an interview.
Look for explicit boundaries, prioritization and an ability to explain trade-offs to application owners. Seniority includes reducing risk for other engineers.
Test transferable concepts first, then verify essential provider-specific experience for the role. State which skills are mandatory.
Yes, under a transparent policy. Require the candidate to verify the output, explain permissions and handle a changed requirement.
Reproducibility, review turnaround, change failures and recovery readiness. Compare a service’s own baseline over time rather than ranking engineers by deployment volume.
Prepare one incident timeline, one risky infrastructure plan and one release acceptance checklist. Those artifacts make a hiring conversation concrete. Discuss the engineering responsibility with AppZime Technologies when you need help defining a staffing or delivery scope.
Current-source note: documentation was reviewed on 18 October 2026. No recent hiring-effectiveness study was verified. Older engineering practices are cited for their established reasoning, not presented as new announcements.
Our AI will analyze your requirements and match you with vetted developers from our global talent pool efficiently and accurately
Drag and drop your PDF or DOCX here, or click to browse
Supported formats: PDF, DOCX (Max 10MB)
Takes ~15 seconds · No signup required
Our AI neural network is processing your requirements across millions of data points
Extracting key requirements and technical specifications
Identifying required technologies, frameworks, and expertise levels
Scanning our global database of pre-screened professionals
Applying proprietary algorithm to find best-fit matches
Ranking and selecting top candidates for your review
AI-powered matching based on your requirements
Unlock full roster with detailed profiles, interview recordings, and salary expectations.
Fill in your details to unlock full candidate profiles and connect with top talent.
 Mobile App Development
 AI & ML
 IT Consulting
 Website Development
 Digital Transformation
 Software Development
 DevOps & Cloud Solutions
 Product Design & Ideation

 Hire Nodejs Developer
 Hire ReactJs Developer
 Hire AngularJs Developer
 Hire Flutter Developer
 Hire VueJs Developer
 Hire Android Developer
 Hire iOS Developer
 Hire Python Developer
 Hire DotNet Developer
 Hire Laravel Developer
 Hire PHP Developer
 Hire CodeIgniter Developer
 Hire Golang Developer
 Hire ROR Developer
 Hire SalesForce Developer


Comments (0)
No comments yet.
Leave Your Comment: