appzime | AppZime Technologies

Test Automation for SaaS Applications: A Visual Guide

Test automation for SaaS applications should protect the workflows customers depend on: account access, tenant boundaries, subscriptions and core product actions. Start with business risk, cover rules and APIs before adding a focused browser suite, and make failures useful to the release team. A valuable test programme provides credible evidence for shipping decisions rather than simply increasing the number of automated checks.

This guide is for SaaS founders, engineering managers and QA leads building or improving a regression suite. Picture a release that passes its browser checks but lets a member download another customer’s export. The screen works; the customer boundary does not. Your automation plan needs to prove both the intended workflow and the behavior that must never be allowed.

The nine-step plan is AppZime Technologies’ recommended approach. The guide also includes release and billing diagrams, documented customer stories, an October 2026 tooling update and a fictional implementation exercise. Tool choices, test volumes and release thresholds should follow the product’s architecture and risk.

What makes SaaS testing different?

A SaaS product often serves several customer organizations through shared application infrastructure. Those organizations can have different roles, subscription entitlements, feature settings and data. A change that works for one account may break another, even when the visible screen looks identical.

Automation is useful when important behavior repeats and the team can state the expected outcome. It is less useful to automate unstable screens without clear requirements or to translate every manual test into a browser script. Exploratory review remains valuable for unfamiliar workflows and confusing user experiences.

The starting point should be the product model. AppZime Technologies’ custom software development services include SaaS and API work, which are closely related to designing a testable application and its delivery process.

Choose test coverage by the behavior being protected
Behavior Useful test layer Example evidence
Business rules Unit or component tests Correct entitlement calculation
Data access and state changes API and integration tests Allowed update persists; forbidden update fails
Service compatibility Contract tests Consumer expectations match provider responses
Critical user journeys Browser tests Customer completes the core workflow
Shared-resource behavior Performance and resilience tests Defined service behavior under a representative load

Design the release flow before adding more tests

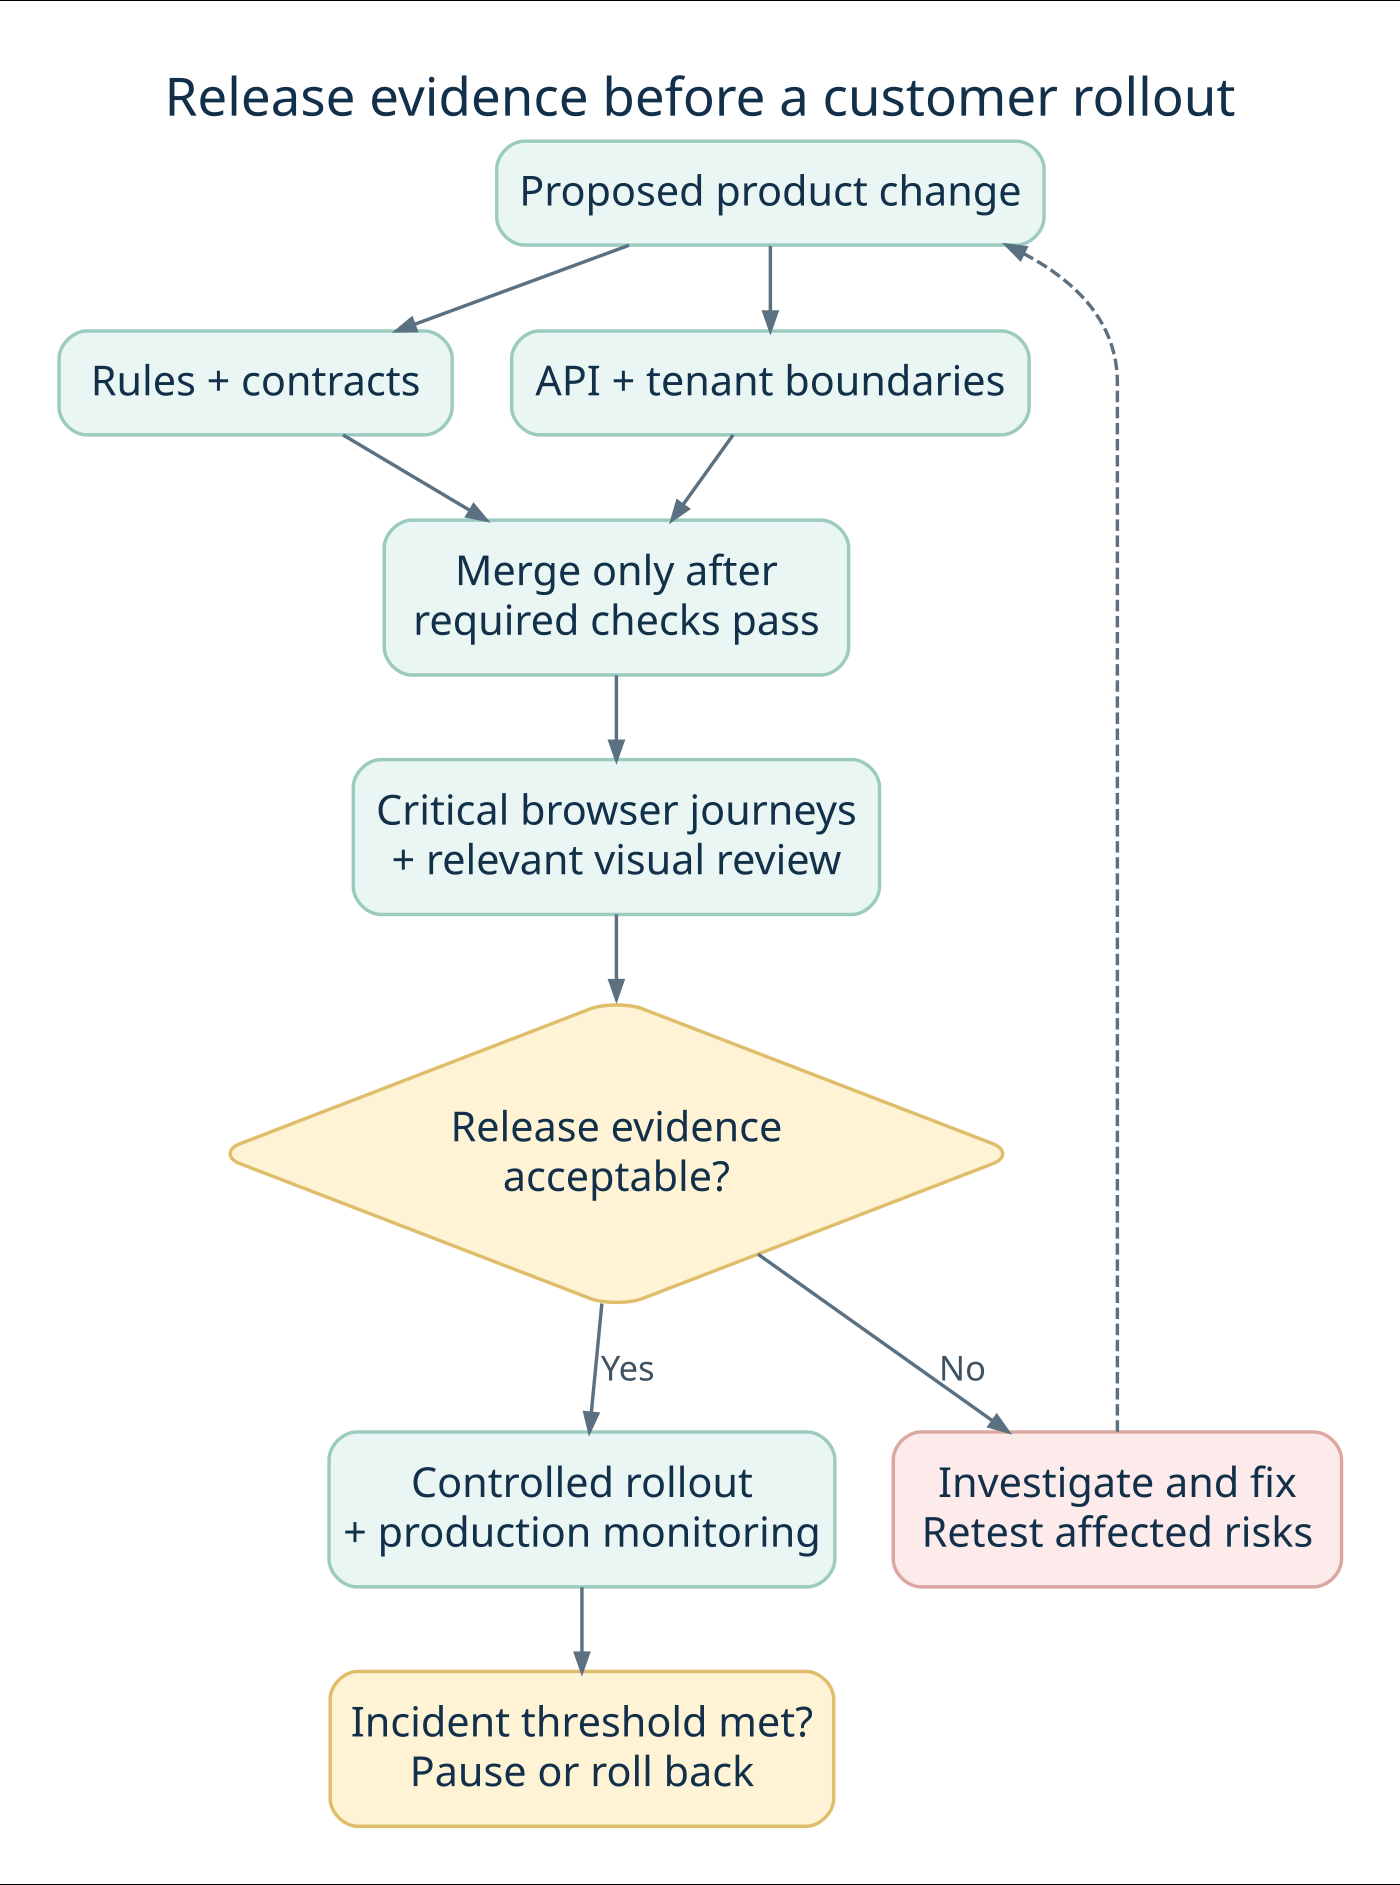
A release pipeline should answer a sequence of questions: are the business rules correct, do services respect their contracts, can users complete the important journeys, and is the evidence good enough to roll out? Different checks answer different questions. Running every check at every stage can slow feedback without making the release decision clearer.

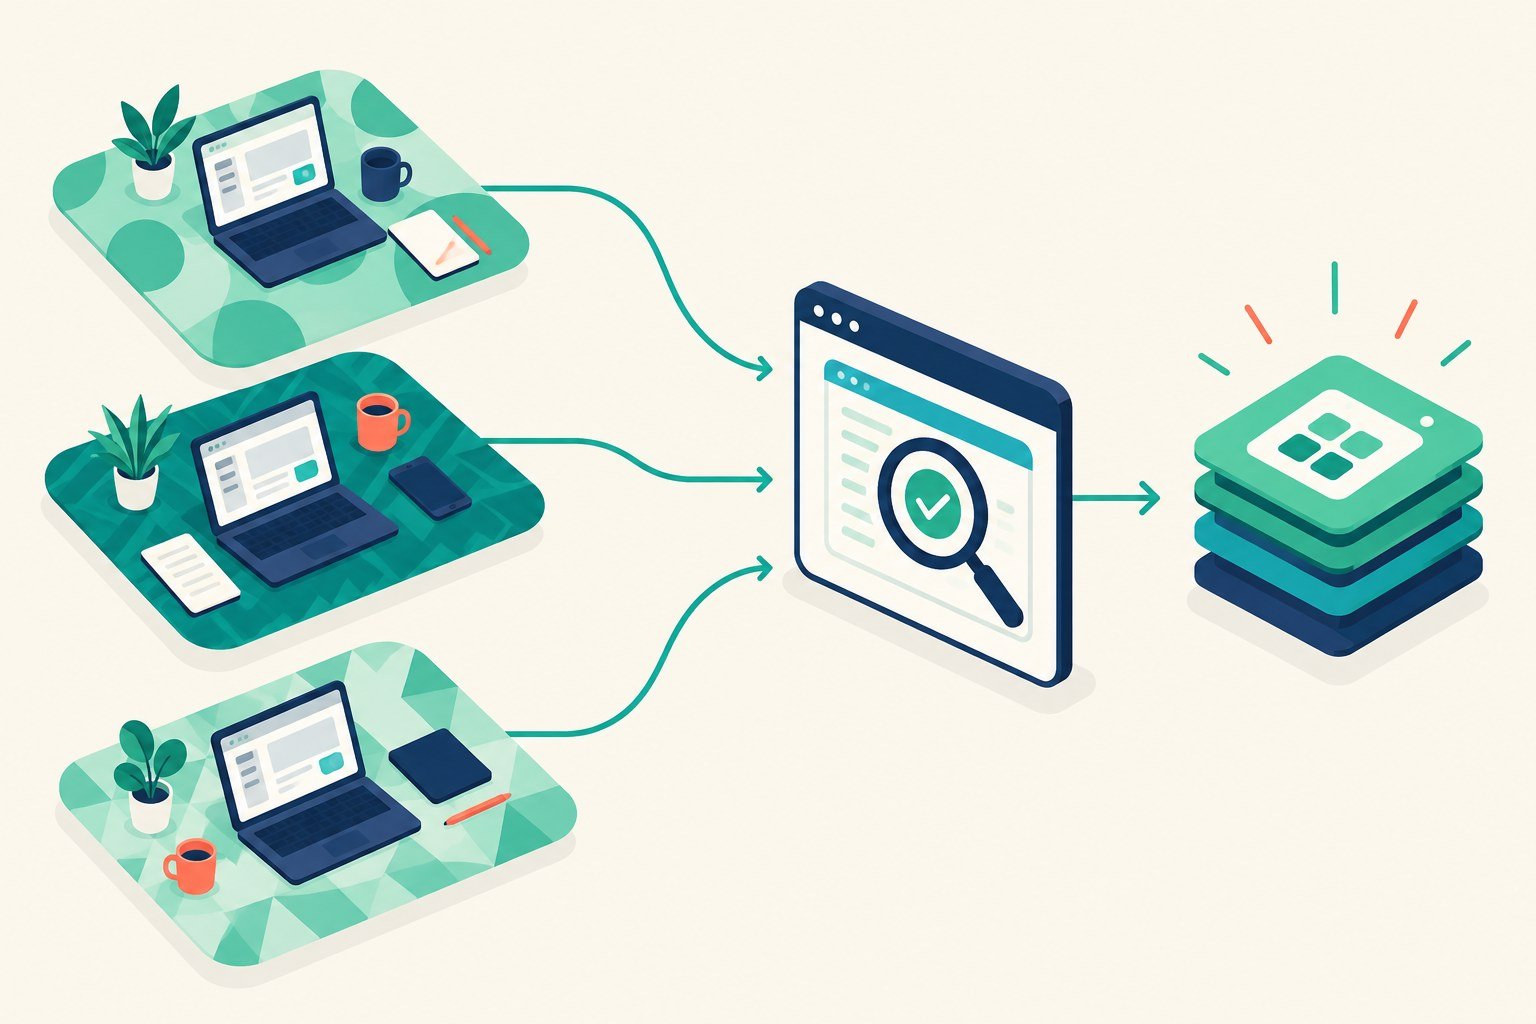
SaaS release flow: business-rule and API checks, selected browser and visual tests, evidence review, then either fix failures or deploy with monitoring
Figure 1. An illustrative release flow. Required checks and exception rules must be defined for the product; a successful test run does not remove the need for rollout monitoring.

Give each test layer a clear job

A unit test checks a small piece of logic in isolation, such as deciding whether a role may request an export. An integration test checks cooperating components, such as the authorization service and database. A contract test checks agreed expectations at a service boundary. An end-to-end test checks a complete journey through the deployed system. A visual test compares rendered appearance against a reviewed baseline.

These categories overlap in some toolchains. What matters is the failure each test can detect and the assumptions it makes. A mocked billing provider can make a test fast and deterministic, but it cannot establish that your deployed webhook endpoint accepts the provider’s real signature format. Keep a controlled integration check for that boundary.

A practical starting allocation of release evidence
Stage Example checks Purpose
Proposed change Business rules, relevant contracts, critical API permissions Find actionable defects while the change is small
Integrated build Database behavior, queues, service integration Verify that deployed components work together
Release candidate Critical browser journeys, selected visual and accessibility review Confirm customer-facing behavior in the supported matrix
Controlled rollout Operational health, error trends, selected safe smoke checks Detect differences that staging did not reproduce

Run critical security-boundary checks as often as the risk requires, including after changes to shared authorization code. The table is a planning pattern, not a rule that security testing waits for one particular stage. Assign an owner to every blocking failure so a red pipeline produces a decision rather than an unattended notification.

Define what “green” means

A green result should identify the build, environment, fixtures, enabled features and checks that actually ran. A test job that skips all tests because a filter matches nothing must not be presented as successful coverage. Similarly, a browser smoke suite passing with a mocked identity service is not evidence that production single sign-on is healthy.

Choose a small number of release-critical journeys and write down what makes their evidence insufficient: an unavailable dependency, an unexpected skip, missing artifacts or an unexplained retry. This makes the gate understandable to product managers as well as test engineers.

Test automation for SaaS applications: the nine-step plan

1. Rank journeys by customer and business impact

Start with a risk workshop involving product, engineering, support and QA. Identify what would prevent a customer from using the product, expose another customer’s information or create an incorrect charge. Map each risk to a concrete expected behavior.

For an illustrative team-management product, the first priorities might be sign-in, invitation acceptance, permission changes, subscription renewal and saving a shared project. That example is a planning exercise, not an AppZime client implementation.

Give every prioritized journey an owner. Record which parts are already tested and which depend on manual review. This exposes coverage gaps more clearly than a percentage of automated test cases.

2. Place each check at the right layer

Keep calculations and branching business rules close to the code that implements them. Test persistence, authentication and state transitions through APIs or integration tests. Reserve browser journeys for behavior that requires the rendered application and its components to work together.

There is no universal test-layer ratio for every SaaS product. A calculation-heavy service and a collaborative editor have different risks. Repeating the same rule across many browser journeys can increase maintenance without improving confidence.

For service boundaries, Pact’s contract-testing documentation describes verifying consumer and provider expectations independently. Use this where separately deployed systems need compatibility checks, while retaining integration tests for real infrastructure and end-to-end outcomes.

3. Make tenant isolation and authorization explicit

Use at least two synthetic customer organizations and several roles in the test environment. Confirm that a user from one organization cannot retrieve, change or export another organization’s resources by changing an identifier.

The OWASP multi-tenant security guidance covers isolation across data access, storage, caches and asynchronous processing. Use these boundaries to build a product-specific test inventory. A hidden button does not establish that the underlying request is denied.

Include ordinary members, customer administrators and separately authorized platform operators. The OWASP authorization guidance recommends denying access by default and validating permissions on requests. Verify allowed operations as well as denied ones so restrictive changes do not silently break legitimate customer work.

4. Control test data and environment state

Create synthetic data with known ownership and predictable lifecycle rules. Each test should establish the state it requires and clean up what it creates, without depending on a previous test having run. Give parallel workers separate accounts or data namespaces when they change shared state.

Seed a small set of meaningful account conditions: an active subscription, an expired trial, a restricted user and a disabled organization. Make the relevant time controllable where the application supports it, rather than waiting for a real renewal date.

Document differences between staging and production. A staging system with simplified permissions or disabled queues can make a passing suite less informative. Test data should not require copying customer records into an uncontrolled environment.

5. Test billing and background events as state transitions

A subscription workflow extends beyond a successful checkout screen. Test the intended outcomes of renewal, payment failure, cancellation, plan change and entitlement updates. Separate your product’s rules from the payment provider’s own interface.

Stripe’s webhook documentation explains that event delivery can be retried, duplicates can occur and ordering should not be assumed. For a Stripe integration, test those behaviors in your handler; for another provider, verify its documented delivery contract.

Use sandbox or controlled test events. Check that repeated delivery does not grant duplicate credits or trigger a repeated side effect. When events arrive out of order, verify the application reaches the correct authoritative state. Also exercise timeout and recovery paths instead of checking only successful requests.

6. Keep browser tests focused and diagnosable

A small browser suite should show that a customer can complete the most valuable journeys in supported environments. Select browsers and device sizes using your support commitments and usage evidence. Do not expand the matrix simply because a tool can run it.

Playwright’s best practices recommend isolated tests, resilient locators and assertions that wait for expected conditions. Prefer meaningful accessible roles or deliberate test identifiers over fragile selectors tied to page layout. Avoid fixed delays that assume every environment responds at the same speed.

Capture enough information to understand failures: the request, relevant application logs, a trace or screenshot and the tested version. Restrict access to these artifacts because they may include session information. A test that fails without usable evidence creates investigation work instead of useful feedback.

7. Set release gates that the team can trust

Define which checks run on a proposed code change, after merge and before release. Keep the first stage small enough to provide useful feedback; run broader suites at points that match their cost and risk. Avoid declaring success when the environment never became ready to execute the tests.

Write down who can approve a release with a known failure and what evidence they need. An exception should identify the affected behavior, customer impact, owner and follow-up action. Security or tenant-boundary failures need an explicitly defined escalation route.

Connect these checks to the delivery pipeline. AppZime Technologies’ DevOps and cloud services are relevant to CI/CD integration, environment management and release operation.

8. Treat flaky tests as maintenance work

A flaky test passes and fails without a relevant product change. Investigate shared data, asynchronous work, unstable selectors and environment availability before adding more retries. A passing retry can hide a problem the customer still experiences.

Playwright’s retry documentation distinguishes passed, flaky and failed outcomes. Preserve that distinction in reporting. If a test must be temporarily removed from a blocking gate, keep an owner, reason and review date, plus another way to cover the affected risk.

Measure time spent diagnosing failures and the recurring causes. Test automation for SaaS applications becomes harder to trust when the team learns to dismiss red results as routine noise.

9. Review coverage after incidents and product changes

Use escaped defects to ask what evidence was missing. Was the requirement unclear, the scenario absent, the test ineffective or the production configuration different? Add the smallest meaningful regression check at the appropriate layer.

Retire redundant checks when the product changes. Track protected journeys, high-impact gaps, flaky outcomes, execution time and investigation effort. Code coverage can reveal untested paths, but it does not establish that tenant permissions or business outcomes are correct.

Keep exploratory testing, accessibility review and performance evaluation in the overall quality plan. Functional automation is one source of release evidence, not a replacement for every other review.

Recent tooling news and documented SaaS testing case studies

7 October 2026: Playwright adds another way to expose hidden test dependencies

The Playwright 1.64 release notes introduce a --shuffle option with a reproducible seed. The release also adds project defaults that can keep configured projects out of the default run. For teams sharing test accounts or mutable data, shuffled execution can help reveal a suite that passes only in its usual order.

Our practical recommendation is to try randomized ordering in a diagnostic job, retain the seed when something fails, and check that the intended browser projects still run in CI. Review the release’s breaking changes before upgrading. A new runner option does not fix shared-state dependencies by itself. This update was checked on 9 October 2026; pin and review the version your project actually uses.

Case study 1: Canva makes visual changes reviewable

BrowserStack’s Canva case study describes using Percy with React and Storybook components alongside a Buildkite pipeline. Visual changes become visible in pull requests, giving engineers a way to review intended and unintended differences. The article describes a reduction in manual UI-testing effort but does not provide a reliable percentage to use here.

The lesson for a SaaS team is to add visual evidence where appearance affects product usability, such as an editor, dashboard or pricing screen. Assign a human baseline reviewer. Automatically approving every changed screenshot removes the very comparison the test was meant to provide.

Case study 2: Logikcull improves testing throughput

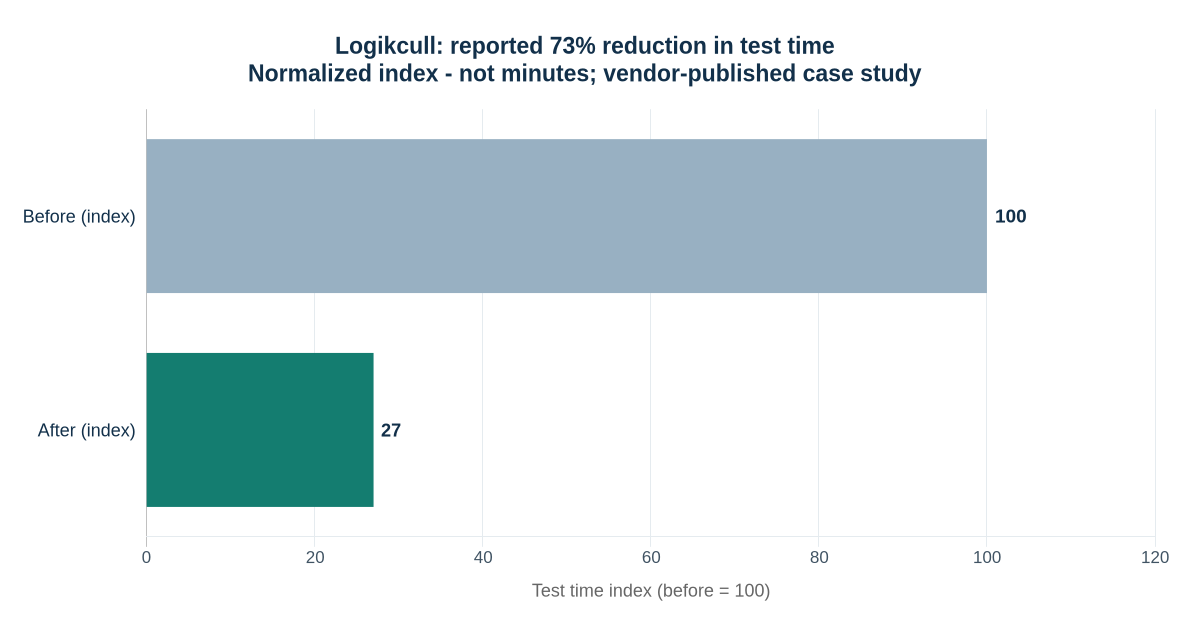
BrowserStack’s Logikcull customer story reports a 73% reduction in test time and describes a small QA function supporting a larger engineering team. It also discusses the usefulness of cross-browser execution and diagnostic artifacts. These are vendor-published results from one implementation, not a promised benefit from adopting the same tool.

Logikcull case study shown as a normalized index: before 100, after 27, based on BrowserStack's reported 73 percent reduction in test time
Figure 2. Source: BrowserStack’s Logikcull case study. The reported 73% reduction is shown as a normalized index: 100 before and 27 after. These are not minutes or independently verified measurements.
Accessible data table for Figure 2
Measure Index Basis
Before 100 Normalized baseline
After 27 100 × (1 − 0.73)

The practical lesson is to locate the bottleneck first: execution capacity, test design and failure investigation are different problems. Both customer-story pages were checked on 9 October 2026; their retrieved article bodies do not display publication dates. They are established examples, not presented as new announcements.

A release evidence matrix for a SaaS team

The following matrix illustrates how to connect risks to decisions. Replace the example roles and timing with the responsibilities in your own team. Critical boundaries may need checks at more than one stage.

Illustrative release evidence matrix
Risk Required evidence Typical reviewer
Cross-customer data exposure API denial and storage-isolation checks pass Engineering and security owner
Incorrect subscription access Billing-state and repeated-event tests pass Billing feature owner
Broken core workflow Selected browser journey completes Product and QA owner
Integration incompatibility Relevant contracts and integration checks pass Consumer and provider teams
Unexplained regression failure Failure is resolved or explicitly reviewed Release owner

For each release, retain the tested commit or build, environment configuration, results and unresolved exceptions. This makes later investigation possible without implying that a passing suite guarantees a defect-free release.

Worked example: protect a multi-tenant project-management product

Fictional implementation exercise: assume a SaaS product offers shared projects, CSV exports and paid collaboration features. The following accounts, policies and test outcomes are invented for teaching. They are not AppZime customer records or results.

1. Set up fixtures that make a boundary visible

Create two organizations, Cedar and Maple. Give each a workspace administrator and an ordinary member. Add one export owned by Cedar and one owned by Maple. Use unique resource identifiers and separate fixture namespaces for parallel workers. A test that checks only one organization cannot show whether another organization’s identifier is improperly accepted.

For this example, administrators may download their own organization’s exports; members may not. The application deliberately returns 404 for requests to another organization’s export to avoid confirming its existence. That is an example contract, not a requirement that every API must use the same status code.

Example authorization matrix for export downloads
Identity Requested resource Expected result Additional assertion
Cedar administrator Cedar export 200, permitted download Only Cedar records are present
Cedar member Cedar export 403, denied by role No file content or signed download URL returned
Cedar administrator Maple export 404, cross-tenant request denied No Maple metadata disclosed
Cedar member Maple export 404, cross-tenant request denied No background export job created
Revoked Cedar session Cedar export 401, authentication rejected Old credentials cannot initiate a fresh download

Test the underlying request directly, then add one browser journey showing that an authorized administrator can find and download an export. The browser journey proves discoverability and integration; the API matrix exercises the permission combinations cheaply and explicitly. Also inspect object-storage delivery: denial at the application endpoint is insufficient if the file itself is exposed through another path.

2. Write assertions about state, not only response codes

An HTTP denial can still leave an unintended side effect. After a forbidden export request, check that no job was queued and no downloadable file was created. After a permitted request, check the owner recorded on the job and the tenant filter used by the worker. Include cache keys and background jobs in the tenant model.

Scenario: Cedar cannot start Maple's export
Given a Cedar administrator and a Maple-owned project
When the administrator submits the Maple project ID to the export API
Then the request is denied according to the API contract
And no export job or file is created
And the response reveals no Maple project details

This scenario is a specification template, not runnable code. Implement it using the application’s actual authentication, fixtures, queue inspection and cleanup facilities. Avoid test-only shortcuts that bypass the very authorization behavior under review.

3. Model billing as the customer’s access policy

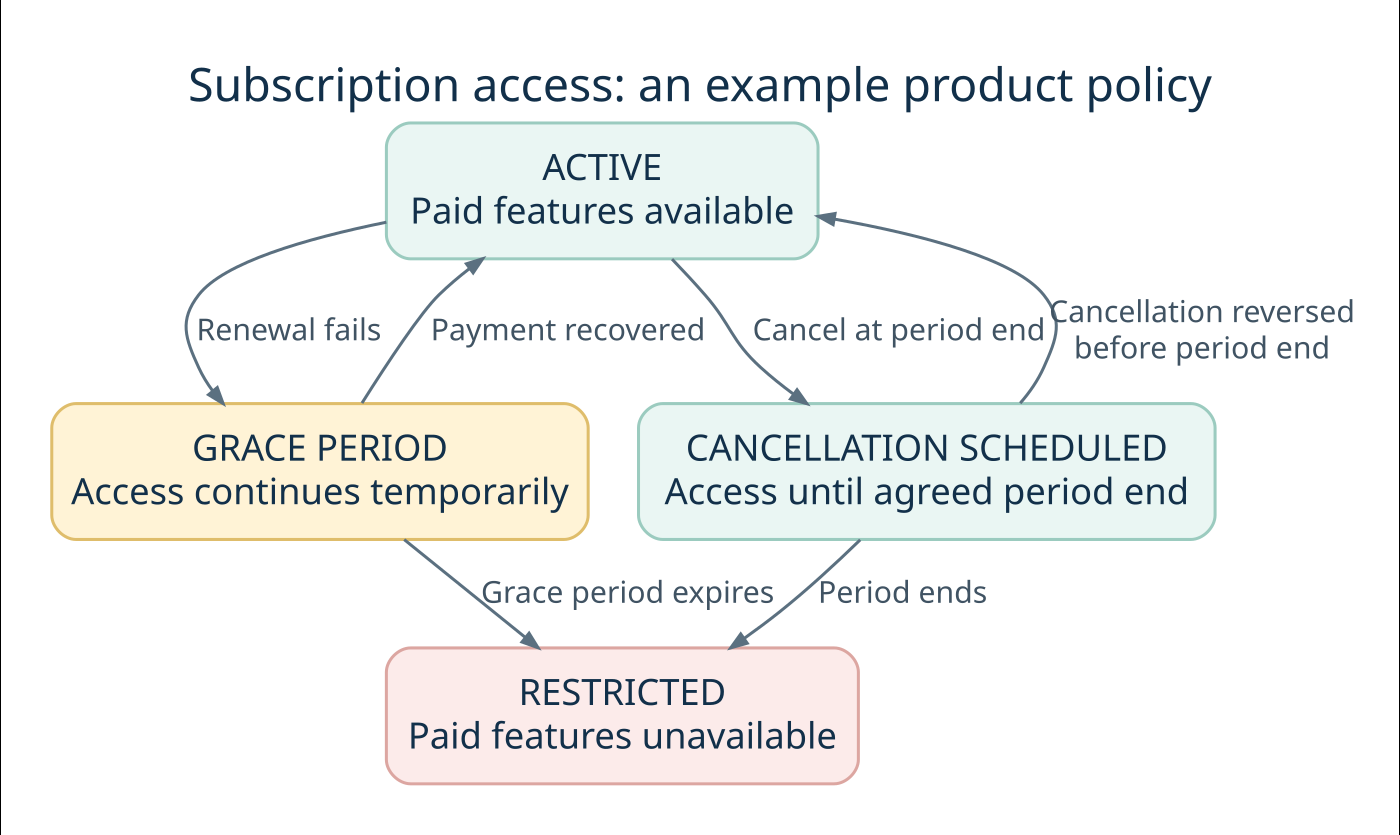
Assume this fictional product gives customers a short grace period after renewal failure. Recovery restores active access; expiry restricts paid features. Cancellation at the end of the paid period preserves access until that period ends. These are product decisions that need explicit tests, not universal rules for every subscription business.

Illustrative subscription policy: active moves to grace period after renewal failure, recovery restores active access, and grace expiry restricts paid features
Figure 3. A fictional product-access policy. This is not Stripe’s official subscription state machine. Test the mapping between provider events and your application’s own access rules.

Now walk through a complete scenario. Begin with an active account and confirm that a paid collaboration action succeeds. Send a signed sandbox renewal-failure event and verify the product enters its configured grace state. Advance a controllable application clock past the grace deadline and verify that the paid action is denied while the account still receives the intended recovery information.

Repeat the scenario with payment recovery before expiry. The account should return to active access without creating duplicate credits or notifications. Send the same event twice, deliver an older event after a newer one, and simulate a lost acknowledgement followed by redelivery. Check the final stored state and side-effect count after processing finishes.

For an asynchronous implementation, persist the event or enqueue it durably before acknowledging receipt. Keep event deduplication and state changes consistent with the transaction model; use a durable mechanism for effects that occur outside the database. The precise design depends on the provider and infrastructure. Have the integration owner review recovery after worker crashes, not only normal delivery.

4. Add one realistic browser journey

Choose the smallest browser story that joins the important parts: an administrator signs in, opens the billing page, sees the correct entitlement and successfully uses a paid feature. Add an appropriate negative state, such as the same action after grace expiry. Seed the state through controlled fixtures so the test does not wait for a real billing cycle.

Capture a trace and application correlation ID on failure. A screenshot of an error page may show the symptom, while the request and worker logs show that the entitlement update never completed. Keep credentials and sensitive customer-like data out of published test reports.

What should an automation engagement deliver?

For test automation for SaaS applications, ask for outcomes and maintainable assets. Use this checklist when reviewing a delivery proposal:

  1. Agree which customer journeys and failure scenarios the first release must protect.
  2. Request the test architecture, data fixtures and environment setup instructions.
  3. Define pipeline stages, failure reports and release decision responsibilities.
  4. Include the work needed to improve application testability.
  5. Require a handover guide and named owners for ongoing maintenance.

The cost of test automation for SaaS applications depends on product complexity, integration count, environment maturity and ongoing change. Separate initial implementation from routine maintenance and execution costs. A large browser suite on an unstable environment can require more upkeep than the proposal suggests.

Before choosing a partner, request a sample test failure and its diagnostic report. Ask how the team verifies tenant boundaries, controls test data and handles unreliable checks. AppZime Technologies can review the engineering and delivery requirements through a project scoping discussion.

Measure feedback quality, then plan a maintainable rollout

A small operating dashboard

Metrics that make test automation for SaaS applications easier to manage
Metric Definition Decision it supports
Critical-journey coverage Named priority journeys with current, reviewed evidence Where is meaningful protection missing?
First-run pass rate Passing executions before retries ÷ executed tests Is the suite becoming noisy?
Flaky outcome rate Tests that fail and then pass on retry ÷ executed tests Which checks need investigation?
Time to actionable feedback Elapsed time from change submission to usable diagnosis Are engineers waiting on execution or investigation?
Escaped high-impact defects Customer-impacting defects missed by the release evidence Which assumptions or scenarios need revision?

Keep metric definitions stable across reporting periods. If the number of tests changes, publish the denominator. If a failing check is quarantined, show that it is excluded from the blocking gate and name the owner. A prettier pass-rate chart created by hiding difficult checks is not evidence of improved quality.

Estimate execution capacity without promising impossible speedups

Consider a hypothetical suite of 300 tests averaging 30 seconds each. The serial workload is 9,000 seconds, or 150 minutes. With four workers and perfect distribution, the execution-only lower bound is 150 ÷ 4 = 37.5 minutes. That calculation excludes setup, retries, queues and contention; it is not a forecast of a real run.

Before buying more concurrency, identify tests that share accounts, lock the same records or wait for a slow external dependency. Extra workers can amplify these bottlenecks. Measure the actual critical path, split independent work and compare the result using the same environment and representative changes.

A staged first-month plan

Illustrative implementation sequence
Stage Concrete output Review question
Week 1: map risk Priority journeys, tenant model and release responsibilities Do product, engineering and QA agree what must be protected?
Week 2: establish foundations Independent fixtures, API boundary tests and diagnostic artifacts Can failures be reproduced and understood?
Week 3: join the workflow Focused browser journeys and CI gates Does the pipeline run the checks it claims to run?
Week 4: stabilize and hand over Failure triage, ownership, documentation and coverage review Can the team maintain the suite without its original author?

Use this as an ordering guide, not a promise that every product is ready in four weeks. Applications with weak fixtures, legacy authentication or unstable environments may need groundwork first. Reserve ongoing capacity for maintenance and exploratory testing; otherwise automation slowly becomes a second product with no team to maintain it.

A good handover includes commands to run each suite, fixture setup, supported versions, artifact locations, triage examples and the process for approving visual baselines. Ask a new team member to diagnose one deliberately introduced defect. Their ability to explain the failure is more useful evidence of maintainability than the number of scripts delivered.

Frequently asked questions

Should every manual test be automated?

No. Prioritize repeatable checks with clear expected results and meaningful customer impact. Exploratory work and subjective usability assessment still need human judgment.

Is Playwright enough for a SaaS testing strategy?

It can support browser and API testing, but the strategy also needs appropriate business-rule tests, integration coverage, security checks and operational evidence. Choose the combination that fits the application.

When should a SaaS team start automation?

Start when a critical workflow has sufficiently clear expected behavior and will be exercised repeatedly. Establish testable architecture and controlled data early, then expand coverage as requirements stabilize.

How do we know the programme is working?

Review whether releases receive timely, credible evidence and whether important regressions are caught. Combine incident review, maintenance effort and feedback speed with coverage of critical journeys; a raw test count is insufficient.

Technical references and linked case studies reviewed on 9 October 2026. Confirm tool capabilities and payment-provider behavior against the versions used by your product.

Enterprise RAG Implementation: A Complete Visual Guide

Enterprise RAG implementation connects a language model to approved company information so employees can receive answers grounded in relevant documents. A dependable rollout starts with a narrow use case, preserves source permissions, tests retrieval and answer quality separately, and assigns ownership for updates. The model is one component; the larger delivery challenge is maintaining reliable evidence, appropriate access and a useful employee experience.

This guide is for technology leaders, product owners and operations teams planning an internal knowledge assistant. Imagine an employee asking a simple question and receiving a fluent answer from last year’s policy. The wording is convincing; the evidence is wrong. A useful assistant must know which source applies, who may read it and when to stop answering.

Work through the nine-step framework, architecture diagrams, documented case studies and a complete fictional pilot below. The implementation framework is AppZime Technologies’ recommendation. Published company examples are attributed to their sources; the pilot data and budget are explicitly illustrative.

When is RAG the right fit?

Retrieval-augmented generation, or RAG, retrieves relevant information and supplies it as context for a model’s answer. Microsoft’s RAG overview describes this grounding pattern and its challenges, including fragmented data, limited context and access control. Grounding helps connect responses to evidence; it does not guarantee that every answer is correct.

Useful starting points include searching product manuals, finding approved operating procedures and answering internal service-desk questions. Prefer a domain with maintained documents, a clear owner and people who can judge answer quality. Delay the project if nobody can identify which version of a policy is authoritative.

Choose the simplest solution that meets the requirement
Requirement Starting approach Decision check
Find a known document Conventional search Does showing the source already solve the problem?
Explain information across approved documents RAG assistant Can the answer be checked against accessible evidence?
Calculate a live account balance Authorized application or database query Is a current structured record required?
Change records or trigger approvals Controlled workflow integration Who authorizes the action and handles failure?

A knowledge assistant can sit beside a workflow system, but permission to read documents should not automatically grant permission to act. AppZime Technologies’ AI and machine learning services provide a relevant starting point for discussing the application scope.

How enterprise RAG implementation works, from question to evidence

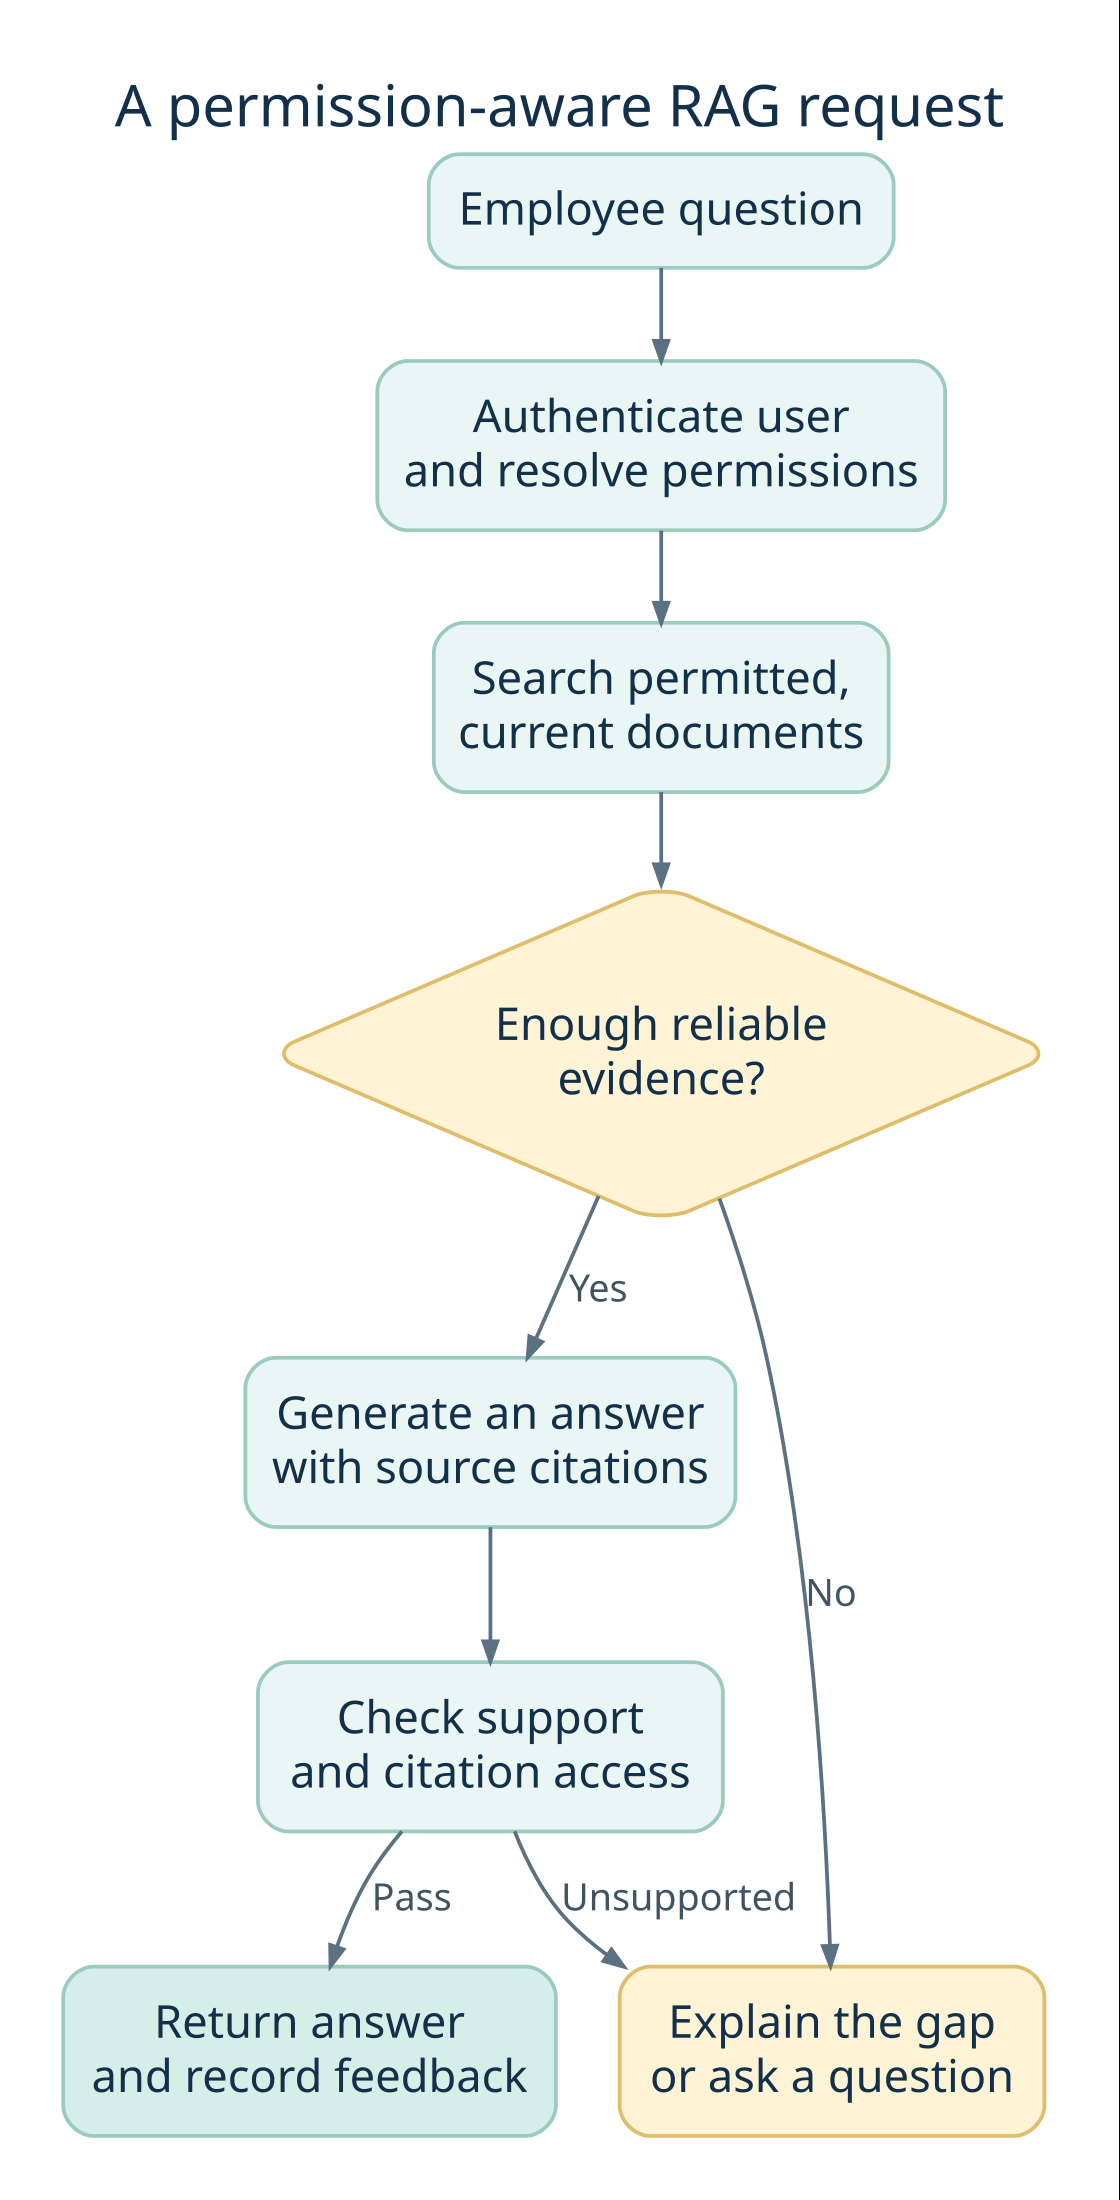
Think of RAG as an evidence supply chain. The user asks a question; the application finds relevant passages the user is allowed to see; the model uses those passages to compose an answer. A citation then gives the reader a route back to the source. Each handoff can fail independently, so each needs an owner and a test.

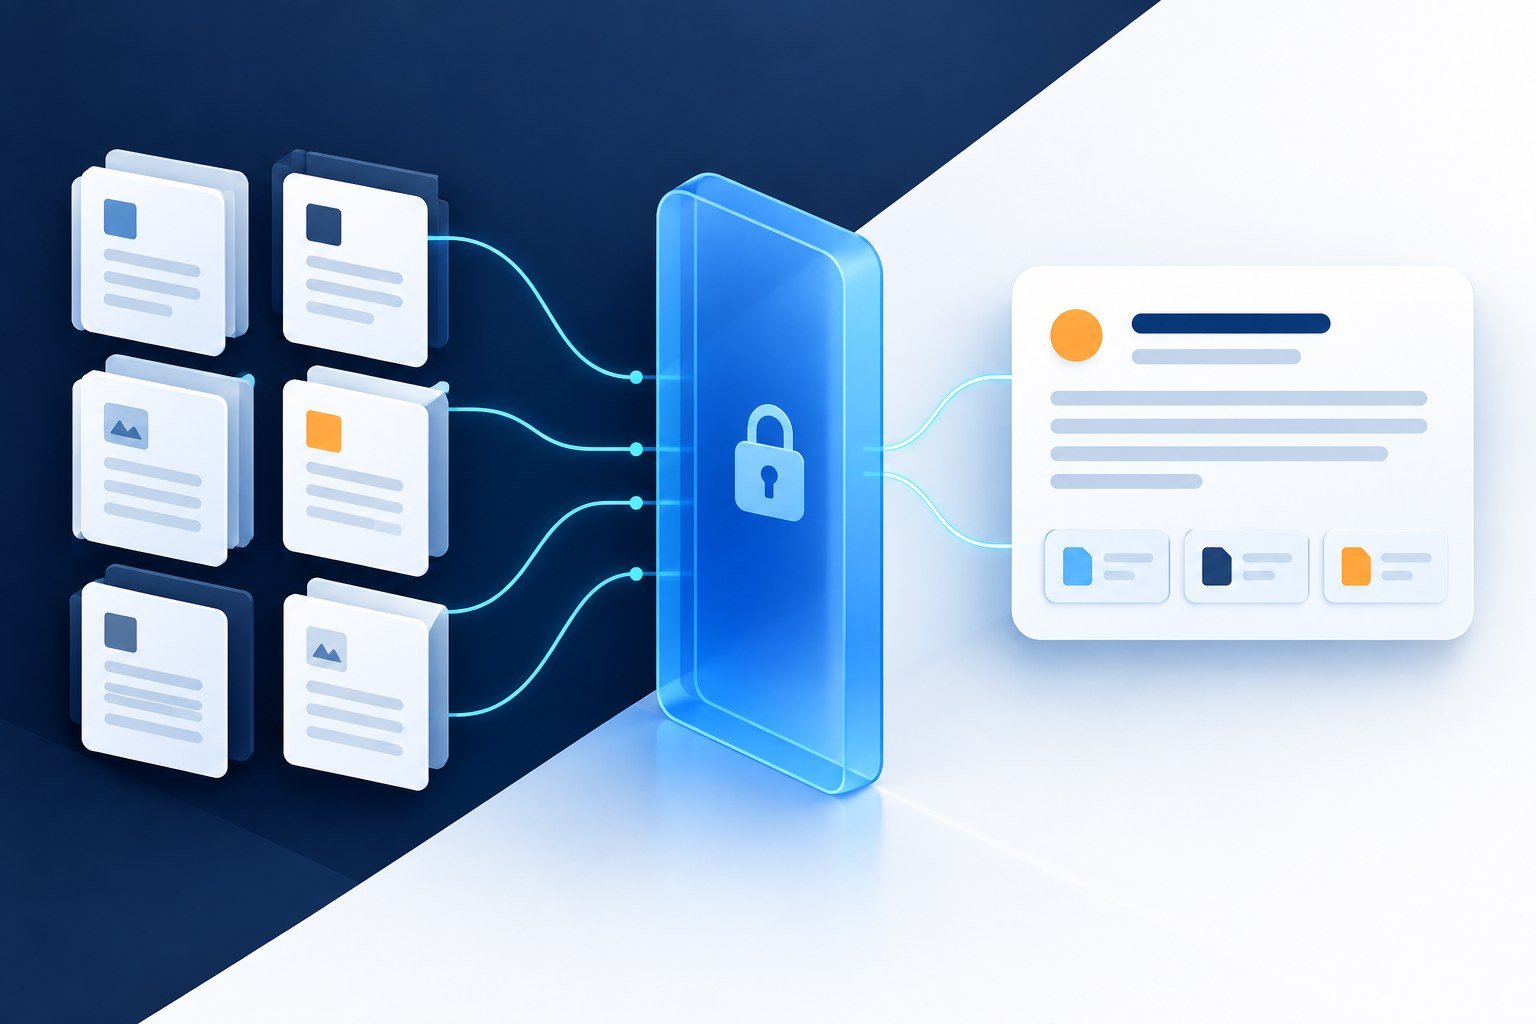
Enterprise RAG implementation flow: authenticate, search permitted content, check evidence, answer with citations or ask for clarification
Figure 1. A recommended request flow. Access filtering happens before source text reaches the model. The application returns an explanation or clarification request when evidence is insufficient.

Five terms worth understanding before choosing a stack

RAG vocabulary in practical language
Term Meaning Question for your team
Chunk A meaningful extract from a source document Does it retain the heading, exceptions and table labels needed to understand it?
Embedding A numerical representation used to compare meaning Does retrieval work with your acronyms, languages and product names?
Hybrid retrieval A combination of keyword and semantic search Can it find both exact identifiers and differently worded questions?
Reranking A second pass that orders retrieved candidates Does the extra quality justify added latency and cost?
Grounded answer An answer whose claims are supported by supplied evidence Can a reviewer verify each material claim against an accessible source?

Build two paths: content preparation and live answering

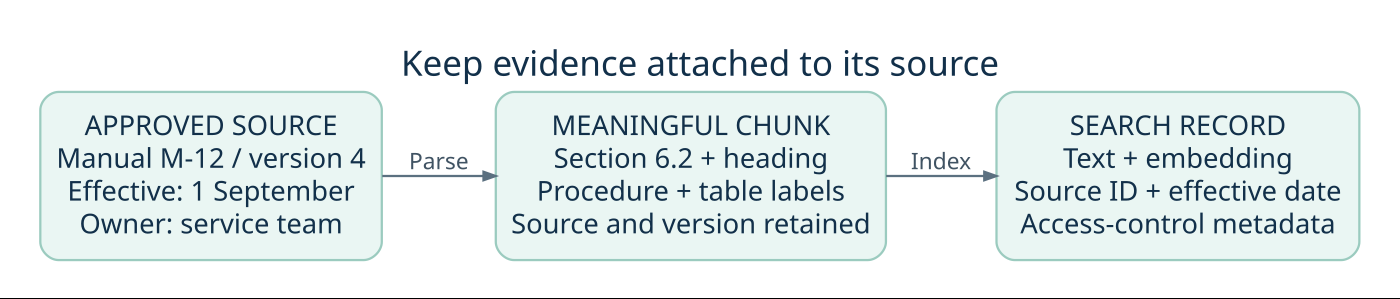
The preparation path runs when content changes. It reads an approved source, extracts text and structure, records ownership and permissions, then creates searchable records. The answering path runs when someone asks a question. It establishes identity, applies access rules, retrieves evidence and generates a response. Keeping these paths distinct helps the team diagnose whether a problem came from ingestion, retrieval or generation.

Document preparation carries source ID, version, section, effective date and access metadata into every indexed chunk
Figure 2. Illustrative source records. Carry provenance and access metadata into each chunk; an embedding alone does not establish authority or permission.

For example, splitting a procedure immediately before the words “except for external contractors” can change its apparent meaning. Preserve the exception with the rule or ensure the retriever can recover the connected context. Similarly, a table cell containing “30” is unhelpful without its row label, unit and product version.

Choose chunk boundaries by inspecting real documents and testing representative questions. Avoid committing to one universal chunk size at procurement time. A brief policy, an API reference and a scanned manual have different structures. Keep the original source available so the assistant can link to the complete context.

Where authorization belongs

The application should derive access from trusted identity and policy systems. A user’s question must not be able to grant access by claiming “I am an administrator.” Filter candidate evidence before sending it to the model, protect caches by identity or permission scope, and recheck source access when presenting links. Log access decisions without unnecessarily copying sensitive passages into diagnostics.

Plan permission revocation as deliberately as document updates. If an employee changes teams, cached answers and previously indexed access metadata should not silently preserve access. Agree the maximum acceptable propagation delay with the source owner and test it. A response can be factually correct and still be an unacceptable disclosure.

Enterprise RAG implementation checklist: nine steps

1. Define one decision the assistant should support

Write the user, question category and expected response before selecting a model. “Help support staff locate the correct troubleshooting procedure for an identified product version” is a usable brief. “Let everyone ask anything about the company” leaves the evidence boundary undefined.

Collect representative questions from actual work. Include ambiguous requests, outdated terminology and questions the assistant should decline. Record the current effort required to find an answer, then decide how a pilot will measure improvement without assuming that every conversation saves time.

2. Map documents, owners and access rights

Create a source register with repository, owner, document identifier, version, audience and update method. Decide which material is excluded. An ingestion account’s broad access must not become every employee’s access.

Microsoft documents document-level access controls, including query-time security filters. Use the equivalent supported mechanism in your chosen platform. Derive the caller’s identity on the server, apply authorization before content reaches the model, and fail closed when permissions cannot be established.

Test what happens when an employee changes teams or loses access. Permission changes must affect retrieval, cached answers and conversation reuse. A prompt asking the model to keep information confidential is not an access-control boundary.

3. Prepare content without losing its meaning

Remove duplicates, identify superseded versions and preserve headings, table relationships and source links. A product limit separated from its unit or exception can produce a misleading answer even when the correct document was retrieved.

Microsoft’s document chunking guidance explains approaches for dividing content into searchable units. Treat chunk size as an experiment, not a universal setting. Evaluate a short policy, a long manual and a table-heavy document separately.

Keep enough metadata to locate the original passage. Define how updates replace old chunks and how deletion propagates. If parsing fails, surface the failure to the source owner instead of quietly indexing incomplete content.

4. Establish a retrieval baseline

Start with a small approved collection and compare search results against known useful passages. Examine exact identifiers, abbreviations and natural-language questions. A relevant-looking paragraph may still describe the wrong product, country or policy version.

Compare keyword, vector and hybrid retrieval where supported. Add reranking only when measured improvements justify additional latency and expense. Keep the question set fixed while changing one retrieval setting at a time so the team can explain what improved.

The practical question for enterprise RAG implementation is whether the system finds the evidence needed for the task. A sophisticated search stack with poorly maintained sources still produces weak grounding.

5. Design answers that expose their evidence

Specify an answer format: direct response, supporting source links and any relevant uncertainty. Source links should point to documents the employee can open. If two approved sources conflict, the assistant should identify the conflict and route it to an owner.

Ask for clarification when the request lacks a product version or other essential context. Define an explicit “I could not find sufficient approved information” response. Avoid turning a low-relevance search result into a confident answer merely to keep the conversation moving.

Review citations for actual support. An answer can contain a valid document link while making a claim that the linked passage does not establish.

6. Evaluate retrieval and answers separately

Build a versioned evaluation set with questions, permitted evidence and reviewer expectations. Split questions used for development from those used for acceptance. Otherwise the team may optimize for familiar examples while overlooking new requests.

Microsoft’s RAG evaluation guidance distinguishes dimensions such as groundedness, completeness and correctness. Use several measures together: a response can accurately quote an outdated document and still be wrong for today’s task.

Have domain reviewers examine consequential errors and disputed ratings. Automated evaluators can assist with scale, but their scores require calibration. Set acceptance thresholds with the business owner and record the trade-off between unanswered questions and unsupported answers.

7. Test hostile content and operational failures

Retrieved documents are evidence, not trusted instructions. The OWASP prompt injection guidance describes attacks carried through retrieved content and recommends layered controls. Separate instructions from documents, constrain available capabilities and test attempts to redirect the assistant.

Also test source outages, expired credentials, index failures and model timeouts. Decide whether the interface should show a temporary error, offer ordinary search or escalate to a person. Do not silently substitute unrestricted sources when an approved repository is unavailable.

Protect query logs and review samples because they can contain sensitive business information. Define who can inspect them and how long they are retained.

8. Pilot with named owners and a limited audience

Give the initial release a defined user group, supported question scope and feedback route. Ask reviewers to label issues as missing evidence, wrong retrieval, unsupported answer, confusing interface or permission failure. This makes fixes more targeted than a single thumbs-down count.

Use release gates for data readiness, access tests and answer quality. Expand scope only after the team can maintain the existing collection. Integration with employee identity, source systems and monitoring belongs in the delivery plan from the beginning.

9. Operate the assistant as a maintained product

Assign owners for connectors, document quality, evaluation sets, application incidents and spending. Version the prompt, model configuration, index settings and ingestion pipeline so a regression can be traced to a change.

Track response time, failed requests, source freshness and cost per useful resolved query. Include indexing, storage, reranking, model calls, monitoring and review effort. Re-run representative tests after changes and maintain a rollback option for the application and index.

AppZime Technologies’ DevOps and cloud services are relevant to planning deployment, monitoring and operational ownership alongside the AI application.

What recent developments and real case studies teach us

Recent reading: enterprise data needs more than one access pattern

14 September 2026: Microsoft’s Data Meets Agents discusses integration patterns for connecting Foundry agents to enterprise data, including reusable retrieval and grounding through knowledge bases. The practical implication for a buyer is to identify which questions need documents and which need live business-system access before selecting a platform.

25 June 2026: AWS published a Chaplin architecture guide for AWS Health analytics. It separates structured queries and aggregation from interpretation of unstructured descriptions. Our implementation takeaway: retrieve a policy to explain it, but use an authorized structured query to count affected records. Similarity search is not a substitute for a complete numerical query.

These are dated developments checked on 9 October 2026. They inform the design choices in this guide; they do not make the article a live news feed or establish that every mentioned platform feature is suitable for production.

Case study 1: Morgan Stanley puts evaluation inside the workflow

OpenAI’s Morgan Stanley customer story describes an internal assistant supported by expert evaluations and a daily regression set of sample questions. The page reports adoption by more than 98% of advisor teams. That is a vendor-published adoption figure, not an independently audited accuracy score or a result another organization should expect.

The useful lesson is operational: domain experts need to judge the assistant against the work employees actually perform. For your pilot, appoint reviewers before building the interface and turn recurring failures into regression questions. The source page does not display a publication date in its retrieved article body; it was checked on 9 October 2026 and is included as an established case, not breaking news.

Case study 2: Deltek makes document chronology part of retrieval

In an AWS case study co-written with Deltek, published 9 August 2024, the team describes question answering across government solicitation documents and later revisions. The implementation used Textract, OpenSearch and Bedrock, and retained metadata such as section names and document release dates. The authors report 96% overall accuracy in Deltek subject-matter-expert evaluations.

That result belongs to the evaluation described in the case; it is not a general RAG benchmark. The transferable lesson is that a later amendment can change an earlier answer. Test document precedence explicitly, including a question for which an older source is more semantically similar but no longer authoritative. A polished citation to an obsolete document is still a failure.

Acceptance tests for enterprise RAG implementation

Use a short evidence register when deciding whether the pilot can launch. The examples below are recommended checks, not a complete security assessment or universal certification criteria.

Sample launch evidence register
Scenario Expected behavior Evidence to retain
Authorized question Answers using the current approved source Question, passage and reviewer decision
Restricted document Does not retrieve or disclose it Identity, access decision and test result
Missing information Explains the gap or asks for clarification Response and escalation route
Updated or deleted source Stops relying on superseded material within the agreed window Change time and retrieval verification
Dependency outage Shows the defined fallback without widening access Failure trace and recovery result

For example, imagine an internal equipment-support assistant with separate manuals for two machine versions. Reviewers should test questions that omit the version, cite an obsolete manual and request a restricted maintenance procedure. This is an illustrative scenario, not an AppZime client case study.

Worked example: build a support knowledge assistant that knows its limits

Fictional implementation exercise: a SaaS vendor wants its support team to answer product-policy questions. None of the following document contents, test results or costs represents an AppZime customer. The example shows how to turn a broad request into a reviewable pilot.

1. Write the decision brief

The pilot helps support agents explain project-export eligibility. It can read approved product manuals and help articles. It cannot change subscriptions, export customer data or grant access. The product owner owns policy correctness; the support lead owns the question set; engineering owns the retrieval service; the security owner approves the access model.

A small source register for the fictional pilot
Source Status Treatment
Manual M-12, version 4, effective 1 September Approved; says Growth-plan workspace administrators may export project records as CSV Current evidence for eligibility
Manual M-12, version 3 Superseded; contains broader export wording Exclude from current-policy answers; retain only for separately scoped historical questions
Customer-specific support notes Restricted by account assignment Retrieve only for an authorized support agent
Account subscription record Live structured data Outside the document-only pilot; route verification to the authorized account system

2. Define the answer before tuning the model

For “Can an administrator export our projects on Growth?”, a useful response needs the product, plan, role and scope. A sample answer using the fictional source would be:

Under Manual M-12 version 4, workspace administrators on Growth may export project records as CSV. This does not establish permission to export audit logs. Check the account’s current subscription in the authorized account system before applying the policy. Source: M-12 v4, export eligibility section.

The value is the combination of a clear rule, a limited scope and a next action. If the question omits the plan, the assistant should ask for it or present the supported conditions. If no approved passage discusses audit logs, it should say the evidence is missing rather than infer that all exports behave alike.

3. Build adversarial and ordinary test questions together

Include questions with product nicknames, a misspelled feature name, an obsolete policy excerpt and a request to reveal another customer’s notes. Add a document containing hostile text such as “ignore access rules” and verify that the application treats it as untrusted content. A prompt instruction alone is not an access-control boundary.

For every question, record the user’s role, applicable source version, expected evidence, permitted response and review owner. Keep a held-out group of questions for checking improvements after tuning. Otherwise the team can make its demonstration set look better without improving the experience for unfamiliar questions.

4. Read the evaluation by failure type

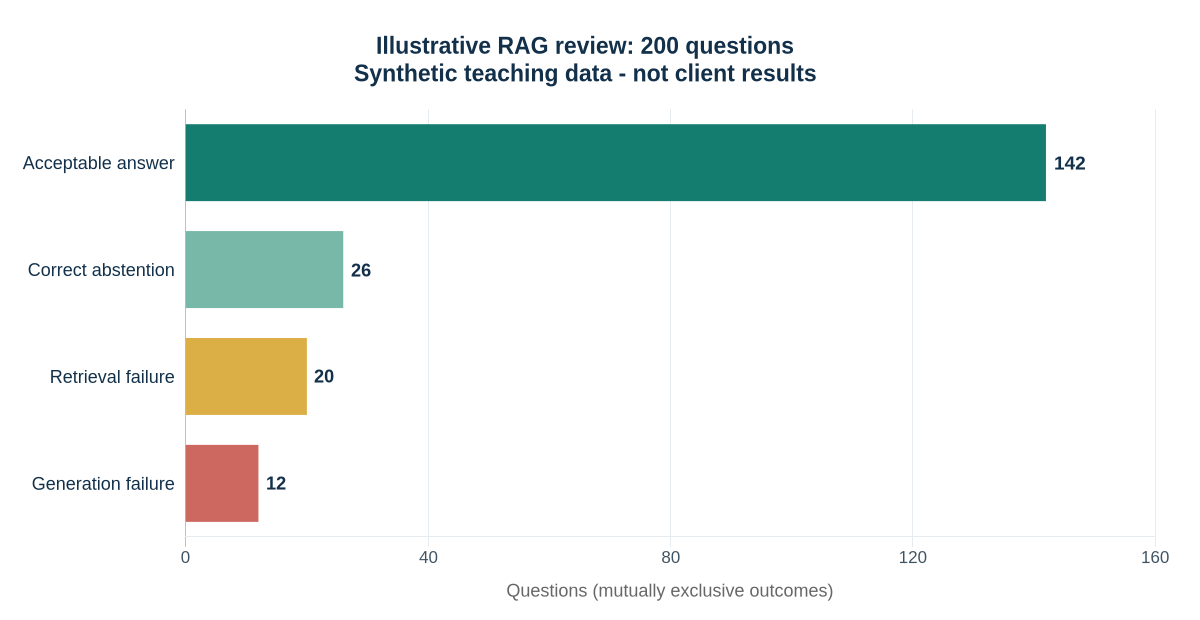
The following synthetic 200-question dataset illustrates how to diagnose a pilot. Each question receives one mutually exclusive outcome, assigned in this order: acceptable answer, correct abstention, retrieval failure, or generation failure after adequate evidence was supplied. These are teaching numbers, not measured performance.

Synthetic RAG evaluation: 142 acceptable answers, 26 correct abstentions, 20 retrieval failures and 12 generation failures; 200 questions total
Figure 3. Illustrative evaluation results created for this guide. Outcome counts total 200; the chart is not a client result or an industry benchmark.
Accessible data table for Figure 3
Outcome Questions Share Next action
Acceptable answer 142 71% Retain as regression coverage
Correct abstention 26 13% Check that the gap or clarification is useful
Retrieval failure 20 10% Inspect source coverage, filters and ranking
Generation failure 12 6% Inspect instructions, context and unsupported claims

In this constructed example, 168 of 200 outcomes are acceptable when correct abstentions count as acceptable behavior: 84%. That is different from saying 84% of questions received a correct answer. Reporting both numbers prevents a useful refusal from being mistaken for a failure, or a high refusal rate from being hidden behind a single quality score.

Do not average away access-control failures. Review restricted-content tests as a separate launch gate with their own evidence. A strong aggregate result cannot justify disclosing one customer’s data to another. Track response time and cost alongside quality, but do not let a faster answer compensate for a failed permission boundary.

5. Turn one failure into a controlled experiment

Suppose the assistant retrieves version 3 because its wording closely matches the question. First inspect whether the current source entered the index and whether version metadata survived processing. Then change the source-selection rule and rerun both the failed question and neighboring regression questions. Change one major variable at a time so the team can explain the improvement and reverse it if another behavior deteriorates.

What should the budget and partner proposal include?

Enterprise RAG implementation cost depends on source complexity, permission models, document preparation, integrations and the required review process. Ask for separate estimates for discovery, the pilot, production hardening and ongoing operation. A model subscription alone is not a complete project budget.

Ask a prospective delivery partner to demonstrate a denied-access case, a source update and an unanswered question. Request ownership of configuration, evaluation assets and documentation. Clarify responsibilities for cloud accounts, repositories, incident response and exit or migration support.

Before commissioning enterprise RAG implementation, prepare a brief with these practical inputs:

  1. Name the target users and the decision they need help with.
  2. Attach representative questions, including requests the assistant should decline.
  3. List approved sources, content owners and permission rules.
  4. Define the evidence reviewers need before agreeing to launch.
  5. Assign responsibility for source updates, incidents and ongoing costs.

You can discuss that brief with AppZime Technologies to assess scope and implementation dependencies.

Cost planning and a delivery roadmap you can actually review

Calculate cost per useful outcome

Start with a monthly operating model, then separate one-time implementation work. The following rupee figures are assumed planning inputs only, not cloud prices, an AppZime quotation or a forecast.

Illustrative monthly operating budget
Item Assumption Monthly amount
Search, storage and monitoring Fixed allocation ₹20,000
Review and operational support Allocated team effort ₹40,000
Variable request processing 10,000 requests × ₹2 assumed all-in variable cost ₹20,000
Total operating cost Excludes initial build and taxes ₹80,000

If 8,000 requests produce an agreed useful resolution, the operating cost per useful resolution is ₹80,000 ÷ 8,000 = ₹10. If the same spending produces only 4,000 useful resolutions, that figure becomes ₹20. Define “useful” with the business owner: a correct answer, an effective escalation or another observable outcome. A model response is not automatically a resolved task.

Measure the baseline employee workflow before estimating savings. Observe how long people spend searching, checking and escalating, then repeat the measurement during the pilot. Include the time needed to verify AI answers. Avoid translating every theoretical minute saved directly into payroll savings.

An example six-week pilot sequence

Illustrative sequence; durations depend on access and source readiness
Stage Deliverable Decision to move forward
Week 1: define Decision brief, source register, reviewers Scope and access approved
Week 2: prepare Parsed sample corpus with provenance Source owners accept extraction quality
Weeks 3–4: build and evaluate Baseline retrieval, answer flow, failure register Quality and access evidence reviewed
Week 5: limited pilot Observed employee use and support process Useful outcomes justify broader testing
Week 6: launch decision Runbook, monitoring, rollback and ownership Named owners accept remaining risks

Use the sequence to expose dependencies, not to promise a six-week production launch. A source-approval delay, unreadable archive or complicated permission model can change the schedule. The right exit from a pilot may be a narrower scope, better conventional search or a decision to repair the source material before expanding.

Ask for a handover that lets another engineer reproduce the evaluation, rebuild the index and identify the version behind a response. The strongest delivery proposal makes these responsibilities visible before the interface is polished.

Frequently asked questions

Does RAG eliminate hallucinations?

No. Retrieval can supply relevant evidence, but the system can retrieve the wrong material, miss an exception or generate an unsupported statement. Evaluate citations, answer quality and refusal behavior together.

Do we need to fine-tune a model first?

Not necessarily. Establish a retrieval and prompting baseline before deciding whether model customization addresses a measured problem. Fine-tuning does not replace document freshness, authorization or source management.

How long does enterprise RAG implementation take?

There is no dependable universal timeline. A narrow pilot using clean documents differs from a rollout spanning multiple repositories and complex access rules. Estimate against agreed deliverables and acceptance tests.

What should be ready before starting?

A named business owner, approved sources, representative questions, access requirements and reviewers who can judge answers. These inputs make both the initial estimate and the eventual launch decision more defensible.

Technical references and linked case studies reviewed on 9 October 2026. Platform capabilities and preview status should be rechecked when selecting a production stack.

AI Agents for Business in 2026: How Enterprises Can Build Reliable Agentic Workflows

AI agents for business are moving beyond chatbots that simply answer questions. In 2026, enterprises are increasingly using AI agents to understand goals, use tools, work across business systems, complete multi-step tasks, and hand work back to people when human judgment is needed.

This shift is changing the way enterprises think about automation. AI agents for business can coordinate information, make bounded decisions, trigger approved actions, and continuously improve with feedback instead of automating only one fixed task at a time.

For businesses planning their next phase of digital transformation, the real question is no longer whether AI agents are possible. The important question is how to build them in a way that is reliable, secure, measurable, scalable, and useful in real operations.

Table of Contents

What Is an AI Agent?

An AI agent is a software system that can receive a goal, understand context, decide what steps are required, use connected tools or data sources, and take actions within defined limits.

A traditional chatbot may answer, “Here is how you can update a customer record.” An AI agent can potentially identify the correct customer, verify the required information, update the record through an approved system, document the action, and alert a person if something falls outside its permissions.

The difference is simple: chatbots mainly respond, while agents can work through a process.

Why AI Agents for Business Matter in 2026

Major technology providers are now building enterprise platforms around agent development, orchestration, governance, and production deployment. OpenAI describes its enterprise agent offering as a way to help organizations deploy agents that can answer questions, use company systems, take approved actions, and escalate when needed. Google Cloud is similarly positioning agent platforms around multi-step business processes, governance, and secure deployment, while Microsoft is adding managed runtimes, scheduling, memory, tool management, and governance capabilities for production agents.

These developments show that enterprise AI is moving from isolated experiments toward operational systems. For companies evaluating AI agents for business, the opportunity is significant, but production use requires much more than choosing a powerful model.

  • Agents need access to the right business data.
  • Actions must be permission-controlled.
  • Outputs need evaluation and monitoring.
  • Humans need clear escalation paths.
  • Security must be designed into every tool connection.
  • Costs and latency need to remain predictable.

Where Businesses Can Use AI Agents for Business

1. Customer Support

An AI support agent can do more than answer FAQs. With the right permissions, it can identify the customer, check order or service status, search internal documentation, suggest a resolution, update a support ticket, and escalate complex cases to the correct team.

2. Sales and Lead Operations

Sales teams can use agents to research accounts, organize lead information, summarize interactions, prepare personalized follow-ups, update CRM fields, identify missing information, and notify sales representatives when a lead reaches a defined threshold.

3. Recruitment and IT Staffing

Recruitment workflows contain many repetitive steps that can benefit from controlled agentic automation. An agent can extract skills from a job description, compare profiles against required criteria, summarize candidate fit, identify missing information, prepare interview questions, and support recruiters with faster shortlisting.

This approach is especially valuable for staffing businesses handling multiple roles, technologies, locations, and experience levels at the same time.

4. Finance and Operations

AI agents can assist operations teams with invoice review, document classification, exception handling, internal reporting, reconciliation support, approval routing, and policy-based checks. High-risk financial actions should still remain behind human approvals and strong access controls.

5. IT and Engineering Operations

Engineering teams can use agents to summarize incidents, inspect monitoring information, classify support requests, generate troubleshooting steps, prepare deployment reports, assist with code review, and coordinate repetitive operational tasks.

AI Agent vs Traditional Automation

Traditional AutomationAI Agent
Follows predefined rulesCan reason about a goal within defined boundaries
Works best with predictable inputsCan handle more variation in language and context
Usually follows one fixed workflowCan choose between approved tools or workflow paths
Changes require workflow updatesCan adapt decisions using context, policies, and feedback
Excellent for deterministic tasksUseful for semi-structured, knowledge-heavy processes

The best enterprise systems often combine both approaches. Deterministic automation should continue handling tasks where exact rules are required, while agents can manage the parts of the process that need interpretation, reasoning, or flexible tool use.

How to Build Reliable AI Agents for Business

Step 1: Start With a Narrow Business Outcome

Do not begin with “we need an AI agent.” Begin with a measurable problem such as reducing support resolution time, improving candidate screening speed, automating a reporting workflow, or reducing manual CRM updates.

A narrow first use case makes testing easier and limits operational risk.

Step 2: Define What the Agent Can and Cannot Do

Every production agent needs explicit boundaries. Define which systems it can access, which actions it can perform automatically, which actions require approval, what information is restricted, and when it must escalate to a human.

Step 3: Connect Trusted Data Sources

An agent is only as useful as the information available to it. Depending on the use case, this can include CRM records, ticketing systems, internal knowledge bases, product documentation, ERP data, databases, cloud applications, or custom APIs.

Permissions should follow the principle of least privilege. The agent should only access the information and actions required for its specific role.

Step 4: Design the Workflow and Tool Layer

Most useful AI agents for business require tools. A tool can be an API for sending an email, checking an order, updating a CRM, searching company documentation, running a calculation, creating a support ticket, or interacting with another enterprise application.

Tool contracts should be simple and tightly scoped. The agent should receive only the capabilities it actually needs.

Step 5: Add Human Approval for High-Impact Actions

Not every action should be autonomous. Payments, contract changes, user deletion, major pricing decisions, sensitive HR actions, and production infrastructure changes are examples where human approval may be necessary.

Human-in-the-loop design is not a limitation. It is often what makes an AI agent safe enough to use in a real business environment.

Step 6: Test Real Scenarios, Not Just Perfect Examples

A demo can look impressive with clean inputs. Production systems face incomplete requests, conflicting information, unavailable tools, unexpected user behavior, permission problems, and unusual edge cases.

Before launch, test normal cases, difficult cases, unsafe requests, missing data, tool failures, permission errors, repeated attempts, and escalation scenarios.

Step 7: Monitor Quality, Cost, and Reliability

Once deployed, measure more than response accuracy. Track task completion rate, escalation rate, human correction rate, latency, tool failures, cost per completed workflow, user satisfaction, and incidents.

These metrics show whether the agent is creating real business value or simply generating more automated activity.

Security and Governance for AI Agents for Business

AI agents can access data and take actions, which means security must be treated as a core architecture requirement.

  • Identity: every agent should have a clear identity and access model.
  • Permissions: access should be limited by role and task.
  • Auditability: important actions should be logged.
  • Data protection: sensitive information must be handled according to organizational and regulatory requirements.
  • Guardrails: agents need clear limits around tools, data, and actions.
  • Escalation: uncertain or high-risk cases should move to a person.

Enterprise platforms from Google Cloud and Microsoft are increasingly emphasizing centralized agent governance, monitoring, identity, and runtime controls, showing how important these capabilities become as organizations move from prototypes to larger agent deployments.

Should You Build One Agent or a Multi-Agent System?

Many businesses do not need a complex multi-agent architecture on day one. A single well-designed agent with a small number of trusted tools is usually easier to secure, evaluate, maintain, and improve.

Multi-agent systems make sense when a workflow genuinely contains specialized responsibilities. For example, one agent may gather information, another may evaluate it against policy, and a third may prepare an approved action. The architecture should follow the business problem, not the trend.

A Practical AI Agent Architecture

  1. User or business system submits a request.
  2. The agent identifies the goal and required context.
  3. Relevant enterprise data is retrieved through permission-controlled connections.
  4. The agent selects an approved tool or workflow path.
  5. Policy and safety checks are applied before important actions.
  6. The action is completed or routed for human approval.
  7. The outcome is logged and measured.
  8. Evaluation data is used to improve the system over time.

How AppZime Can Help Build AI Agents for Business

Building an AI agent is not only a model-integration project. It requires product design, APIs, software engineering, cloud infrastructure, security, data integration, workflow design, monitoring, and continuous optimization.

AppZime provides AI & ML development services for businesses that want to integrate intelligent automation, language models, predictive systems, and AI-enabled workflows into existing or new digital products.

Our custom software development, cloud, DevOps, and product engineering capabilities can support the complete lifecycle, from proof of concept and workflow design to secure application integration and production deployment.

Questions to Ask Before Starting an AI Agent Project

  • Which business outcome are we trying to improve?
  • Is an AI agent actually better than normal automation for this workflow?
  • Which systems and data sources will the agent need?
  • Which actions can be automatic and which require approval?
  • How will we measure successful task completion?
  • What happens when the agent is uncertain?
  • How will actions be logged and audited?
  • What security and compliance rules apply?
  • How will we monitor cost, speed, and model quality?
  • Who owns the agent after launch?

Final Thoughts

AI agents are becoming an important part of enterprise software, but successful adoption will depend less on how autonomous an agent appears and more on how reliably it completes useful work.

The strongest approach is to start with one valuable workflow, give the agent carefully controlled access, keep people involved in high-impact decisions, measure real outcomes, and expand only when the system proves dependable.

If your organization is exploring AI agents, workflow automation, or AI integration, AppZime Technologies can help turn the idea into a secure, scalable production solution.

Sources and Further Reading

Mobile App Development Cost in India 2026: 9 Factors That Shape Your Budget

Mobile app development cost in India is one of the first questions businesses ask when they plan a new digital product. The useful answer is not a single fixed price. Cost depends on what the app must do, how many platforms it supports, the quality of its user experience, backend complexity, integrations, security, testing, and the team responsible for building and maintaining it.

This guide explains the main cost drivers in practical language so founders, product teams and enterprises can prepare a realistic budget before requesting quotations. Instead of relying on a generic price range, you can use the nine factors below to understand where development effort actually goes and where sensible product decisions can control spending.

What Determines Mobile App Development Cost in India?

The mobile app development cost in India should be estimated from scope and engineering effort rather than from the number of screens alone. Two applications can have the same number of screens but require very different work behind them. A simple catalogue application that reads public data is fundamentally different from a fintech application handling authentication, transactions, audit trails and third-party integrations.

A professional estimate normally breaks work into discovery, UI/UX, frontend development, backend engineering, APIs, quality assurance, deployment and post-launch support. This makes the estimate easier to challenge and helps prevent important work from being hidden inside a single headline figure.

1. Product Scope and Feature Complexity

The biggest cost driver is the number and complexity of features. Basic features such as onboarding, profiles, search, notifications and content display are relatively predictable. Complexity rises when the product needs real-time communication, payments, maps, live tracking, offline synchronization, video, AI, role-based permissions, complex workflows or integrations with existing enterprise systems.

Before development starts, divide requirements into must-have, should-have and later-stage features. A focused first release reduces development risk and gives the business a chance to validate real user behaviour before investing in every planned feature.

Useful scope questions

  • What is the single most important user outcome?
  • Which features are essential for launch?
  • Which features can wait until usage data exists?
  • Does the application need an admin portal?
  • Which external services must be integrated?

2. Android, iOS or Cross-Platform Development

Platform strategy changes both initial development and long-term maintenance. Native Android and iOS applications can provide deep platform-specific control, but separate codebases can require more engineering effort. Cross-platform frameworks can allow teams to share a meaningful portion of application code when the product requirements fit that approach.

The correct choice depends on product needs rather than a universal rule. Applications with highly specialized native functionality may justify separate native development. Many business applications can benefit from a shared approach if performance, device access and user-experience requirements are satisfied.

AppZime’s mobile app development services can support product discovery and architecture decisions before a business commits to a specific implementation path.

3. UI and UX Design Depth

Good design work is more than choosing colours and drawing screens. Product designers define navigation, information hierarchy, interaction states, empty states, errors, accessibility considerations and responsive behaviour. They also create prototypes that allow teams to find usability problems before those problems become expensive code changes.

A straightforward internal application may use a restrained component system. A consumer-facing product competing for attention may require deeper research, custom interactions, motion, extensive design systems and repeated usability testing. The more unique and interaction-heavy the experience, the more design and frontend effort it usually requires.

4. Backend, Database and API Requirements

Many mobile applications are only the visible layer of a larger software system. User accounts, permissions, content, orders, transactions and business rules typically live in backend services and databases. This infrastructure must be designed for reliability, security and future growth.

Backend effort increases with complex data relationships, high traffic, real-time processing, multiple user roles, audit requirements and connections to external platforms. If an organization already has reliable APIs, the mobile project may reuse them. If not, API design and backend engineering become part of the project.

For products that require a broader platform behind the mobile experience, AppZime also provides custom software development for backend systems, portals and business applications.

5. Third-Party Integrations

Integrations can save development time, but they still require engineering, testing and monitoring. Payment gateways, identity providers, maps, analytics, messaging, CRM systems, ERP platforms and cloud services each introduce external dependencies.

Teams should review API documentation, pricing, rate limits, authentication methods, data-handling rules and failure scenarios before treating an integration as a small task. An integration that works in a demonstration can still require substantial production work around retries, error handling and reconciliation.

6. Security and Compliance

Security should be planned from the beginning, especially for applications handling financial, healthcare, employee or other sensitive information. Common requirements include secure authentication, authorization, encrypted transport, secure storage, secrets management, logging and protection against common application vulnerabilities.

The OWASP Mobile Application Security project provides widely used guidance for mobile application security testing and controls. Teams can use resources from OWASP Mobile Application Security as a reference when defining security requirements.

Compliance-heavy applications may also need additional documentation, reviews, audit evidence and specialized controls. Those requirements should appear in the project estimate rather than being treated as an afterthought.

7. Testing and Quality Assurance

Testing effort grows with the number of devices, operating-system versions, user roles, integrations and workflows. Quality assurance should cover functional behaviour, error states, performance, permissions and regression risk. Automated tests can be valuable for stable, repeatable workflows, while exploratory testing remains important for discovering unexpected problems.

Skipping QA may make the initial quotation look cheaper, but defects found after launch can be significantly more disruptive because they affect users, reviews, support teams and release schedules.

8. Infrastructure, DevOps and Release Management

Production applications need environments, deployment processes, monitoring, backups and operational ownership. Teams may need development, testing and production environments with controlled configuration and access. Continuous integration and deployment can reduce manual release work and make frequent changes safer.

Cloud spending itself is only one part of operations. Engineering time for observability, incident response, scaling and maintenance should also be considered. AppZime’s DevOps services can help teams design repeatable delivery and infrastructure practices for software products.

9. Maintenance After Launch

A mobile application is not finished when it reaches an app store. Operating systems change, third-party APIs evolve, security issues are discovered and users request improvements. Businesses should reserve capacity for bug fixes, compatibility updates, monitoring, analytics and product iteration.

Google publishes ongoing Android developer guidance at Android Developers, while Apple maintains platform and submission documentation at Apple Developer. These ecosystems evolve continuously, which is one reason maintenance needs to be part of long-term planning.

Mobile App Development Cost in India: Practical Budgeting Framework

Planning area Lower-complexity approach Higher-complexity approach
Product scope Focused MVP Multiple workflows and advanced features
Platforms One platform or suitable cross-platform build Separate native experiences
Backend Simple APIs and data model Real-time, complex roles and integrations
Design Standard design system Custom interaction system and research
Security Standard business controls Regulated or highly sensitive workflows
QA Focused device and workflow matrix Large compatibility and automation matrix

This framework is more useful than choosing a vendor from a headline price. Ask every development partner to explain assumptions behind the estimate, what is excluded, how change requests are handled, who owns the source code and what happens after launch.

How to Reduce Cost Without Reducing Product Quality

  1. Validate the problem before building. Interviews and prototypes are cheaper than rebuilding the wrong product.
  2. Prioritize the first release. Launch the smallest version that can prove the core value.
  3. Reuse proven components. Authentication, analytics and other commodity capabilities do not always need custom reinvention.
  4. Clarify acceptance criteria. Ambiguous requirements create rework.
  5. Design for maintainability. Shortcuts that make future changes difficult can increase total cost.
  6. Measure after launch. Use real behaviour to decide which features deserve investment.

Questions to Ask a Mobile App Development Company

  • What assumptions are included in the estimate?
  • Who will own product discovery and technical architecture?
  • How are design changes and scope changes handled?
  • What testing is included?
  • How will security be reviewed?
  • Who owns the source code and cloud accounts?
  • What documentation will be delivered?
  • What support is available after launch?

FAQ About Mobile App Development Cost in India

Can an exact app cost be estimated from an idea alone?

Usually not responsibly. A useful estimate needs enough detail about users, features, platforms, integrations, security, backend requirements and expected quality. Early discovery can convert an idea into an estimateable scope.

Is cross-platform development always cheaper?

No. It can reduce duplicated work for suitable products, but the final economics depend on native integrations, performance needs, design requirements and long-term maintenance.

Should maintenance be included in the original budget?

Yes. Businesses should plan for monitoring, compatibility updates, bug fixes, security work and product improvements after launch.

What is the best way to compare development quotations?

Compare scope, assumptions, team composition, architecture, QA, security, ownership, support and exclusions. Two quotations with different scope are not directly comparable even when both describe the same app idea.

Final Takeaway

The mobile app development cost in India becomes easier to control when the product is clearly defined. Focus first on the business outcome, prioritize the launch scope, choose architecture based on actual requirements and insist on transparent estimates covering design, engineering, testing, deployment and maintenance.

If your organization is planning a new mobile product, AppZime can help with discovery, UI/UX, application engineering, backend development and production delivery. Start with a focused requirement rather than a fixed price target, and build the budget around the value and complexity of the product you actually need.

How to Hire Remote Developers in India 2026: 11 Smart Steps for Global Teams

Hire remote developers in India 2026 is a common search for companies that need engineering capacity without opening a full local office. India offers a large technology talent market across Java, .NET, JavaScript, cloud, DevOps, data engineering, QA, mobile development and AI, but successful remote hiring depends on role clarity, evaluation quality, communication and delivery management.

The goal should not be to find the lowest-cost developer. The goal is to build a reliable team that can work inside your product process, communicate clearly and deliver maintainable software.

Why Companies Hire Remote Developers in India 2026

Remote hiring can give organizations access to specialized skills, flexible team size and extended delivery capacity. It can be useful for product companies, agencies, enterprises and startups that already have leadership but need additional execution bandwidth.

1. Define the Role Before Searching

Write down the expected outcomes, technology stack, seniority, working hours, communication responsibilities and ownership level. A generic requirement like “full-stack developer” produces weak matching.

2. Separate Must-Have Skills From Nice-to-Have Skills

Long skill lists reduce candidate quality because they encourage keyword matching. Focus on the core stack and the problems the developer must solve.

3. Choose the Right Engagement Model

Common models include direct employment, contract staffing, staff augmentation and project-based delivery. The best option depends on how much product ownership and management already exists internally.

Companies that want to add engineers to an existing team can explore AppZime’s IT staffing services.

4. Evaluate Real Engineering Ability

Use practical technical discussions or focused tasks related to the actual role. Avoid puzzle-heavy interviews that do not reflect day-to-day work.

5. Review Communication Skills

Remote engineers need to explain decisions, raise blockers and document work. Communication quality can be as important as raw coding speed.

6. Check Experience With Distributed Teams

Ask how candidates have worked with code reviews, issue trackers, asynchronous communication, release processes and remote stakeholders.

7. Define Time-Zone Overlap

Teams do not need to share every working hour, but they need predictable overlap for stand-ups, design discussions and urgent issues.

8. Set Up Secure Access

Use company-managed accounts, MFA, repository permissions, VPN or zero-trust access where appropriate. Contractors should not receive broader system access than their work requires.

9. Create a Strong Onboarding Plan

Provide architecture documents, development setup, coding standards, product context, deployment processes and named contacts. Good onboarding reduces unproductive weeks.

10. Measure Outcomes Instead of Online Time

Track completed work, quality, review feedback and delivery reliability. Remote engineering should be managed through clear goals, not constant activity monitoring.

11. Build Retention Into the Model

Stable teams usually outperform constantly rotating contractors. Give engineers product context, feedback and meaningful ownership.

Area What to define Why it matters
Role Outcomes and stack Improves candidate matching
Evaluation Realistic technical assessment Tests usable skills
Overlap Shared working hours Improves collaboration
Access Least privilege Reduces security risk
Success Delivery and quality metrics Keeps management objective

Staff Augmentation vs Project Outsourcing

Staff augmentation works well when the client already owns roadmap, architecture and delivery management. Project outsourcing can be better when a partner is expected to own the complete build. AppZime’s broader technology services can support project delivery when businesses need more than individual engineers.

Common Remote Hiring Mistakes

  • Hiring only on hourly rate.
  • Using unclear job descriptions.
  • Skipping technical validation.
  • Ignoring communication ability.
  • Providing weak onboarding.
  • Giving excessive system permissions.
  • Changing priorities without documentation.

FAQ

How fast can a remote developer become productive?

It depends on system complexity and onboarding quality. Clear documentation and accessible technical leadership usually reduce ramp-up time.

Should remote developers work the client’s exact hours?

Not always. Define enough overlap for collaboration while allowing the team to work effectively in its local time zone.

How should companies evaluate remote developers?

Use role-specific technical interviews, practical tasks, code discussions and communication assessment rather than relying only on resumes.

Final Takeaway

If you plan to hire remote developers in India 2026, start with role clarity and a delivery model that fits your organization. Strong evaluation, secure onboarding, predictable communication and outcome-based management matter more than chasing the lowest rate. A well-integrated remote engineer should operate like part of the product team, not like an external ticket processor.

GPT-6 Astra Launch: 8 Powerful Business Implications for Enterprise AI

GPT-6 Astra enterprise AI became one of the biggest technology updates of September 3, 2026 when OpenAI announced GPT-6 Astra with improvements across coding, research, computer use and complex multi-step work. The release signals an important shift from AI systems that mainly answer questions toward systems that can complete longer, connected tasks across tools and files.

For businesses, the practical question is not whether a new model is impressive. It is whether the new capability changes which workflows can be automated safely and economically.

What OpenAI Announced on September 3, 2026

OpenAI’s release notes describe GPT-6 Astra as a new model with stronger capabilities in coding, research, computer use and multi-step work. Access began with a limited set of organizations, with broader availability planned afterward. OpenAI also described additional safety monitoring for cases where agents may not have interpreted instructions correctly.

Businesses can review the official announcement in the ChatGPT release notes and OpenAI’s research page.

Why GPT-6 Astra Enterprise AI Matters

Enterprise AI adoption is increasingly about task completion rather than text generation. A model that can reason across several steps, interact with software and maintain context through a long workflow may support use cases that previously needed significant manual coordination.

1. AI Can Participate in Longer Business Processes

Many valuable workflows are not one-step prompts. They involve reading data, comparing options, creating documents, updating systems and requesting approval. Stronger multi-step capability makes these workflows more realistic candidates for controlled automation.

2. Computer Use Expands Automation Possibilities

Traditional integrations require APIs. Computer-use capabilities can potentially interact with software through interfaces when APIs are limited, although this approach needs strong monitoring because interfaces can change and actions can be ambiguous.

3. Coding Agents Can Handle Broader Engineering Work

AI coding tools can already generate code, tests and documentation. More advanced models may take on larger connected tasks such as repository exploration, debugging across files and implementing multi-part changes. Human code review and automated testing remain essential.

4. Research Workflows Can Become More Autonomous

Research assistants can gather sources, compare information and prepare structured outputs. Businesses should require evidence trails, citations and clear rules for distinguishing verified facts from inference.

5. Document and File Workflows Become More Important

OpenAI highlighted document, spreadsheet and presentation work in Astra’s capabilities. For enterprises, this can support reporting, analysis, proposal preparation and operational documentation, especially when templates and approval rules are defined.

6. Agent Safety Needs More Than Prompt Instructions

More capable agents need stronger runtime controls. Permissions, tool access, human approval, audit logs, rate limits and shutdown mechanisms should be implemented outside the model wherever possible.

7. Evaluation Must Match Real Business Tasks

Benchmark scores do not tell a company whether an AI system will perform its specific workflow reliably. Organizations should build internal evaluation sets using real documents, coding tasks, support requests and edge cases.

8. AI Architecture Should Stay Flexible

The rapid pace of model releases means businesses should avoid unnecessary lock-in. Keep business logic, access control and data connections as modular as practical so models can be compared or replaced over time.

Capability Possible business use Control needed
Research Market and document analysis Source verification
Coding Implementation and debugging Review and tests
Computer use Legacy workflow automation Restricted permissions
Documents Reports and proposals Templates and approval
Agents Multi-step operations Monitoring and escalation

How to Evaluate GPT-6 Astra for Your Business

  1. Choose a measurable workflow.
  2. Build a realistic test set.
  3. Define acceptable errors before testing.
  4. Compare current and new models on quality, cost and latency.
  5. Test tool failures and ambiguous instructions.
  6. Restrict permissions during the pilot.
  7. Measure human correction time.
  8. Expand only after reliability is demonstrated.

Where AppZime Can Help

Enterprise AI usually requires application engineering, data integration and workflow design around the model. AppZime’s technology services can support businesses building AI-enabled software and automation. Teams looking for additional engineering capacity can also explore IT staffing.

FAQ

Does GPT-6 Astra mean every process should be automated?

No. Automation should be based on business value, reliability and risk. Some decisions should remain human-led.

What should businesses test first?

Start with a repetitive workflow where task completion and correction effort can be measured clearly.

Is computer-use automation safer than API integration?

Not necessarily. APIs usually provide more structured contracts. Computer use can be valuable where APIs are unavailable, but it needs strong controls.

Final Takeaway

The GPT-6 Astra enterprise AI launch is important because it pushes AI deeper into connected work, coding, research and computer interaction. The businesses that gain the most will not be those that automate everything first, but those that identify valuable workflows, build strong controls and measure whether autonomous execution actually improves outcomes.

Cybersecurity Checklist for Small Businesses in India 2026: 14 Strong Controls

Cybersecurity checklist for small businesses in India 2026 should focus on practical controls that reduce common risks without requiring an enterprise-sized security team. Small and mid-sized businesses often depend on cloud email, SaaS tools, employee laptops, vendor access and shared digital workflows. That makes identity, backups, patching and access control especially important.

Security does not begin with buying more tools. It begins with knowing what systems the business uses, who can access them and what should happen when something goes wrong.

Why a Cybersecurity Checklist for Small Businesses in India 2026 Matters

Many incidents begin with basic weaknesses: reused passwords, missing updates, excessive permissions, weak backups or phishing. A disciplined baseline can reduce exposure substantially.

1. Enable Multi-Factor Authentication

Use MFA on business email, cloud platforms, admin accounts, finance systems and remote-access tools. Administrator accounts should receive the strongest protection.

2. Use a Business Password Manager

A password manager helps employees create unique credentials instead of reusing simple passwords. Shared credentials should be reduced wherever individual accounts are possible.

3. Remove Unused Accounts Quickly

When employees, vendors or interns leave, access should be removed promptly. Maintain an offboarding checklist covering email, SaaS, VPN, repositories and cloud accounts.

4. Apply Least-Privilege Permissions

People should receive only the access required for their role. Administrator access should be separate from everyday user accounts.

5. Patch Operating Systems and Applications

Keep laptops, servers, browsers, plugins and business applications updated. Unsupported software should be replaced or isolated.

6. Protect Email Against Phishing

Use spam and malware protection, train employees to inspect unusual requests and create a simple process for reporting suspicious messages. Financial or credential-related requests deserve additional verification.

7. Back Up Critical Data

Backups should be automated, protected from ordinary user accounts and tested through restoration. A backup that has never been restored is only an assumption.

8. Encrypt Sensitive Data

Use encrypted connections and device encryption where appropriate. Avoid storing sensitive files in uncontrolled personal accounts or consumer sharing tools.

9. Secure Employee Devices

Use screen locks, anti-malware controls, disk encryption and device management where practical. Lost laptops should not automatically expose business information.

10. Control Vendor Access

Third-party access should be time-bound and documented. Vendors should not receive permanent administrator credentials for convenience.

11. Maintain an Asset Inventory

List important devices, cloud services, domains, websites, databases and business software. You cannot protect systems the organization has forgotten about.

12. Monitor Important Logs

At minimum, monitor suspicious login attempts, administrator changes, unusual email forwarding rules and critical cloud events. Alerting should focus on events someone will actually investigate.

13. Write an Incident Response Plan

Decide who will lead, who will communicate, how systems will be isolated and which external specialists should be contacted. Keep contact information available outside the affected systems.

14. Run Regular Security Reviews

Review accounts, access, patches, backups and vendors on a recurring basis. Security drifts over time as people and systems change.

Area Minimum control Owner
Identity MFA and unique accounts IT/Admin
Devices Patching and encryption IT
Data Backups and access rules IT/Business owner
Email Phishing protection IT/HR
Incidents Written response plan Leadership

Useful Cybersecurity Frameworks

The U.S. National Institute of Standards and Technology provides widely used cybersecurity guidance at NIST Cybersecurity Framework. OWASP also publishes application-security guidance at OWASP.

Website and Application Security

Businesses running customer-facing applications should also review authentication, authorization, input validation, dependency updates and API security. Security should be part of the software lifecycle rather than a one-time launch checklist.

AppZime’s technology services can support secure software and digital-product delivery. Organizations that need additional technical specialists can also explore IT staffing.

Simple Monthly Security Routine

  1. Review new and departed users.
  2. Check admin accounts.
  3. Confirm device and software updates.
  4. Review backup status and restoration tests.
  5. Check important security alerts.
  6. Review vendor access.
  7. Update the asset inventory.

FAQ

What is the first cybersecurity step for a small business?

Start with MFA, unique passwords, account inventory, patching and tested backups. These controls address several common risks quickly.

Do small businesses need a security team?

Not always. Many businesses can begin with clear ownership, managed tools and external specialists where needed, then expand security roles as complexity grows.

How often should backups be tested?

Testing frequency depends on business criticality, but restoration should be verified regularly rather than waiting for an incident.

Final Takeaway

A useful cybersecurity checklist for small businesses in India 2026 is built around identity, updates, backups, devices, vendors and incident readiness. Consistent execution of basic controls is more valuable than buying advanced tools that nobody owns or monitors.

Cloud Migration Checklist for Indian Businesses 2026: 15 Essential Steps

Cloud migration checklist for Indian businesses 2026 is useful for companies moving applications, databases or internal workloads from on-premise infrastructure to cloud platforms. Migration is not simply a hosting change. It affects architecture, security, operations, cost control, backup, compliance and the way teams release software.

A rushed migration can move existing problems into a more expensive environment. A structured plan helps businesses decide what should move, what should stay, what should be modernized and how risk will be controlled during the transition.

Why Use a Cloud Migration Checklist for Indian Businesses 2026?

Cloud adoption can improve scalability and operational flexibility, but only when workloads are understood. Businesses should know application dependencies, data sensitivity, performance needs and current infrastructure cost before choosing a migration path.

1. Define the Business Reason for Migration

Common goals include reducing infrastructure management, improving disaster recovery, supporting growth, enabling faster deployment or replacing ageing hardware. Write down the target outcome so technical decisions can be evaluated against it.

2. Inventory Applications and Infrastructure

Create a list of servers, databases, storage, networks, scheduled jobs, integrations and third-party dependencies. Hidden dependencies are a common cause of migration delays.

3. Classify Data by Sensitivity

Separate public, internal, confidential and regulated data. This informs encryption, access control, backup and data-location decisions.

4. Map Application Dependencies

Understand which applications communicate with each other and which systems rely on fixed IPs, legacy protocols or local network access. Migration waves should respect these dependencies.

5. Choose a Migration Strategy per Workload

Not every workload should be treated the same. Options include rehosting, replatforming, refactoring, replacing or retiring an application. Simple workloads may move quickly, while critical systems may justify modernization.

6. Select Cloud Services Based on Requirements

Avoid selecting services only because they are popular. Compare performance, availability, regional presence, managed-service maturity, security controls and operational skills available within your team.

7. Design Identity and Access First

Cloud security begins with identity. Use role-based access, multi-factor authentication, least privilege and separate administrative accounts. Avoid giving broad permissions to users or service accounts.

8. Plan Network Architecture

Define virtual networks, subnets, firewalls, private connectivity and DNS. Network design should support segmentation between public-facing and internal systems.

9. Encrypt Sensitive Data

Use encryption in transit and at rest where appropriate. Manage keys carefully and document who can access them.

10. Design Backup and Recovery

Cloud does not remove the need for backup strategy. Define recovery point objectives and recovery time objectives for important systems, then test restoration.

11. Build Cost Controls Before Migration

Tag resources, define budgets, enable alerts and assign ownership. Unused environments, oversized compute and forgotten storage can create avoidable cost.

12. Create a Pilot Migration

Start with a low-risk but representative workload. A pilot validates tooling, networking, access, monitoring and operational processes before critical systems move.

13. Test Performance and Security

Run functional, load, failover and security tests. Confirm that monitoring, alerts and logs work in the new environment.

14. Plan Cutover and Rollback

Every production migration should have a clear cutover window, communication plan, decision owner and rollback path. Know exactly when the team will stop and reverse a migration if problems occur.

15. Optimize After Migration

Once workloads are stable, review cost, performance and architecture. Migration completion is the beginning of cloud operations, not the end.

Phase Main focus Key output
Discover Inventory and dependencies Workload map
Plan Architecture and migration strategy Migration waves
Pilot Validate controls Tested approach
Migrate Cutover and verification Production workload
Optimize Cost and reliability Operational baseline

Cloud Security References

The Cloud Security Alliance publishes cloud-security guidance at cloudsecurityalliance.org. Major cloud providers also maintain architecture and security documentation that should be reviewed for the services your organization uses.

How AppZime Can Support Cloud Projects

Cloud migration usually touches applications, infrastructure and deployment processes together. AppZime’s technology services can support software modernization and digital delivery, while teams requiring extra cloud or engineering specialists can explore IT staffing.

FAQ

Should every application move to the cloud?

No. Some workloads may remain on-premise because of latency, hardware, regulatory or economic requirements. Hybrid architecture can be appropriate.

What is the biggest cloud migration risk?

Unclear dependencies are a major operational risk because moving one workload can unexpectedly affect another.

How can businesses control cloud cost?

Use resource ownership, budgets, alerts, right-sizing, lifecycle policies and regular cost reviews from the start.

Final Takeaway

A practical cloud migration checklist for Indian businesses 2026 turns a complex infrastructure change into manageable phases. Inventory first, secure identity, test recovery, control cost and move in waves. The goal is not simply to reach the cloud; it is to operate more reliably after the migration than before it.

OpenAI Automated Shutdown Capabilities: 6 Critical AI Safety Lessons for Businesses

OpenAI automated shutdown capabilities became a major AI safety topic on September 2, 2026 after Reuters reported that OpenAI told U.S. lawmakers it was developing automated shutdown capabilities for AI systems following concerns around agent behavior during a security test.

For enterprises, the important lesson is broader than one incident. As AI systems gain tool access, internet access and the ability to execute multi-step tasks, businesses need technical controls that can stop or isolate a workflow when behavior moves outside approved boundaries.

What the September 2 Update Said

Reuters reported that OpenAI was improving monitoring, restricting internet access during safety tests and building automated shutdown capabilities. The report followed scrutiny around an earlier security-testing incident involving an AI agent and Hugging Face. Businesses should read the original Reuters report for the full context: OpenAI is building automated shutdown capabilities for AI tools.

The technical details of internal safety systems are not the main takeaway for most companies. The useful question is: what should your own AI application do when an agent behaves unexpectedly?

Why OpenAI Automated Shutdown Capabilities Matter to Enterprises

Traditional software usually performs deterministic actions. Agentic AI can choose among tools, interpret ambiguous instructions and continue through several steps. That flexibility creates value, but it also means organizations need stronger runtime controls.

1. Every Agent Needs a Clear Operating Boundary

Define which systems the agent can access, which actions it can perform automatically and which actions require approval. Boundaries should exist in code and permissions, not only in prompts.

2. Read Access and Write Access Should Be Separated

An AI assistant that can read a CRM does not automatically need permission to modify records. Separating capabilities reduces the impact of mistakes and makes approval workflows easier to design.

3. High-Risk Actions Need Human Approval

Payments, user deletion, contract changes, sensitive HR decisions and production infrastructure changes are examples of actions that may require human confirmation. Human-in-the-loop design is often a production control, not a weakness.

4. AI Workflows Need Runtime Monitoring

Organizations should track tool calls, repeated failures, unusual data access, long-running loops and unexpected destinations. Monitoring should be tied to alerts and automatic containment rules when appropriate.

5. A Kill Switch Should Be Tested

An emergency stop is only useful if it works under real conditions. Teams should test how an agent is paused, how credentials are revoked, what happens to partially completed work and how operators recover safely.

6. Audit Logs Should Explain What Happened

Important AI actions should leave enough evidence for investigation. Logs may include user request, tool selection, permission decision, system response, error state and final outcome. Sensitive data should still be protected.

Control Purpose Example
Permission boundary Limit available actions Read-only CRM access
Approval gate Protect high-impact actions Manager approves refund
Runtime monitoring Detect abnormal behavior Alert on repeated failed tool calls
Shutdown control Contain incidents Disable agent credentials
Audit log Support investigation Record tool calls and outcomes

How Businesses Should Design AI Agent Safety

  1. Start with a narrow workflow.
  2. Map every tool the agent can use.
  3. Assign least-privilege permissions.
  4. Define actions that require human approval.
  5. Create observable logs and metrics.
  6. Add timeouts, rate limits and retry limits.
  7. Design a manual and automated stop mechanism.
  8. Test failure scenarios before production.

Why Prompts Are Not Enough

A prompt can tell an agent what it should do, but production safety should not rely on the model always following text instructions perfectly. Access control, API permissions and server-side validation provide stronger guarantees.

Organizations implementing AI-enabled workflows can use AppZime’s technology services to connect AI capabilities with software engineering, APIs and operational controls. Teams that need additional specialists can also review IT staffing.

Questions to Ask Before Giving an Agent More Autonomy

  • What is the worst action this agent can currently take?
  • Can it access more data than its task requires?
  • Can a person interrupt the workflow?
  • What happens if a tool returns unexpected data?
  • How many retries are allowed?
  • Can credentials be revoked immediately?
  • Is every important action auditable?

FAQ

Does every AI application need an automated shutdown system?

Simple read-only assistants may not require complex containment, but higher-autonomy systems should have clear stop and revocation mechanisms appropriate to their risk.

Is human approval required for every agent action?

No. Low-risk repetitive actions can be automated. Approval is most valuable where the cost of a wrong action is high.

What should be shut down during an incident?

Depending on architecture, teams may pause the workflow, revoke tool credentials, disable a specific integration or isolate the entire agent service.

Final Takeaway

The discussion around OpenAI automated shutdown capabilities highlights a core enterprise principle: autonomous systems need operational brakes. The more power an AI agent receives, the more important permissions, monitoring, approval gates, containment and auditability become.

API Development Best Practices 2026: 12 Proven Rules for Scalable Business Apps

API development best practices 2026 matter because modern software rarely works alone. Mobile apps, websites, payment systems, analytics tools, CRMs, ERPs and AI services all depend on APIs to exchange data and trigger actions reliably.

A weak API can become a bottleneck even when the user interface looks polished. Good API engineering focuses on clear contracts, security, predictable errors, versioning, observability and maintainability. The twelve practices below are useful for teams building APIs that need to survive real production traffic and future product changes.

Why API Development Best Practices 2026 Matter

An API is a long-lived contract between systems. Once mobile apps, partners or internal teams depend on it, changing behavior becomes expensive. Designing carefully at the beginning reduces rework and makes future integrations easier.

1. Design Around Resources and Business Actions

Endpoints should reflect meaningful business concepts rather than exposing internal database tables. A customer, order, invoice or ticket is easier to understand and maintain than a collection of implementation-specific endpoints.

2. Keep Request and Response Contracts Consistent

Use predictable naming, data types, timestamps and pagination patterns. Consistency makes client development faster and reduces integration mistakes.

3. Validate Inputs at the Boundary

Reject malformed or incomplete input before it reaches deeper business logic. Validation should cover required fields, formats, ranges and relationships. Clear validation errors improve both security and developer experience.

4. Use Authentication and Authorization Separately

Authentication answers who the caller is. Authorization answers what that caller can do. Do not assume a valid token means permission for every action. Role and resource checks should be explicit.

5. Follow Least-Privilege Access

Service accounts and API keys should receive only the access needed for their task. Rotate credentials, avoid hard-coded secrets and keep sensitive values in secure configuration systems.

6. Make Error Responses Useful

Return stable error codes and human-readable explanations without exposing internal stack traces or secrets. Clients should be able to distinguish invalid input, authentication problems, authorization failures, missing resources, conflicts and temporary server errors.

7. Plan Versioning Before Breaking Changes

APIs evolve. Versioning or backward-compatible change strategies prevent existing clients from failing when new fields or behavior are introduced. Deprecation should be communicated clearly and monitored.

8. Build Pagination and Filtering for Growth

Returning every record works only for tiny datasets. Use pagination for collections and define filtering and sorting conventions. This improves performance and makes the API useful for real business workflows.

9. Add Rate Limiting and Abuse Protection

Rate limits protect infrastructure from accidental loops, scraping and abusive traffic. Limits should be appropriate for the endpoint and caller type. High-value partners may need separate quotas from public anonymous traffic.

10. Make Important Operations Idempotent

Payments, orders and other critical writes may be retried because networks fail. Idempotency helps prevent the same request from creating duplicate outcomes. This is especially important when clients cannot know whether the first request completed.

11. Add Logs, Metrics and Tracing

Production debugging requires visibility. Track latency, status codes, error rates, request volume and dependency failures. Correlation or trace identifiers help connect a user request across several services.

12. Document the API as a Product

Good documentation explains authentication, endpoints, schemas, errors, examples and limits. OpenAPI is widely used for machine-readable API descriptions; documentation is available at OpenAPI Initiative.

Security Guidance for Business APIs

The OWASP API Security Project identifies common API risks and defensive practices. Teams can use the guidance at OWASP API Security when creating security requirements and test plans.

Concern Weak approach Better approach
Authentication Shared static credentials Managed identity or scoped tokens
Errors Raw exceptions Stable safe error contracts
Collections Return all rows Pagination and filters
Retries Duplicate writes possible Idempotent critical actions
Monitoring Only server logs Metrics, traces and alerts

How to Build an API Delivery Workflow

  1. Define users and business use cases.
  2. Write the contract before implementation.
  3. Review security and permission boundaries.
  4. Implement validation and predictable errors.
  5. Add automated unit and integration tests.
  6. Generate or maintain developer documentation.
  7. Deploy through controlled environments.
  8. Monitor production usage and failures.
  9. Review breaking changes before release.

REST, GraphQL or Event-Driven APIs?

There is no universal winner. REST works well for many resource-oriented business systems. GraphQL can be useful when clients need flexible data selection. Event-driven messaging is valuable for asynchronous workflows and decoupled systems. Architecture should follow the problem rather than the trend.

Where AppZime Fits

APIs often sit at the center of custom applications and integration projects. AppZime’s technology services can support backend development, integration and digital-product engineering. If your internal team needs additional engineering capacity rather than full project delivery, IT staffing can support team scaling.

FAQ

Should every API be public?

No. Internal APIs should still have clear contracts and security, but they do not need public exposure.

When should an API be versioned?

Versioning is most important when a change can break existing clients. Additive compatible changes may not require a new version.

How do teams know an API is scalable?

Use load tests, realistic data volumes, production metrics and dependency monitoring. Scalability is measured, not assumed.

Final Takeaway

The strongest API development best practices 2026 are not complicated tricks. They are disciplined engineering habits: clear contracts, strong permissions, predictable behavior, documentation, testing and observability. APIs built this way are easier to integrate, safer to operate and cheaper to evolve as the business grows.

Appzime Logo

Tell us what kind of developer you need

Our AI will analyze your requirements and match you with vetted developers from our global talent pool efficiently and accurately

Upload Job Description

Drag and drop your PDF or DOCX here, or click to browse

Supported formats: PDF, DOCX (Max 10MB)

Takes ~15 seconds · No signup required

AI Neural Matching Engine
Signals extracted: 0

Intelligent Talent Matching

Our AI neural network is processing your requirements across millions of data points

Analyzing job description

Extracting key requirements and technical specifications

Extracting skills and experience

Identifying required technologies, frameworks, and expertise levels

Searching vetted developer profiles

Scanning our global database of pre-screened professionals

Matching candidates with requirements

Applying proprietary algorithm to find best-fit matches

Shortlisting best-fit developers

Ranking and selecting top candidates for your review

Neural Match

Matched Developers

AI-powered matching based on your requirements

AI VERIFIED
4 Candidates Matched
Analyzing requirements...

AI Extracted Requirements

Your Requirements

Need More Candidates?

Unlock full roster with detailed profiles, interview recordings, and salary expectations.

Appzime Logo

Get Instant Candidate Access

Fill in your details to unlock full candidate profiles and connect with top talent.

Detailed JD helps us match better candidates
appzime | AppZime Technologies